Source: https://x.com/waterloo_intern/status/2081762065392541951
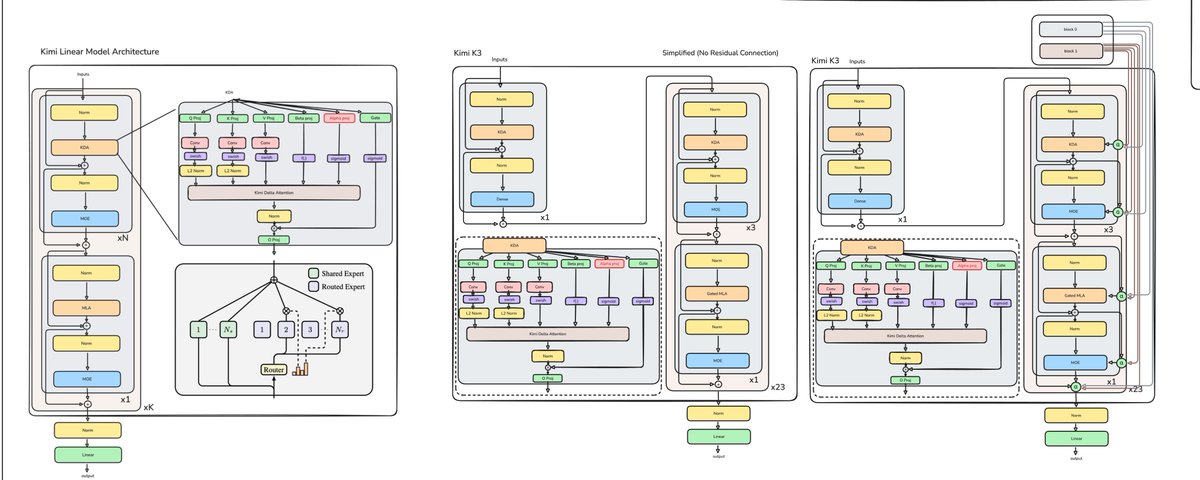
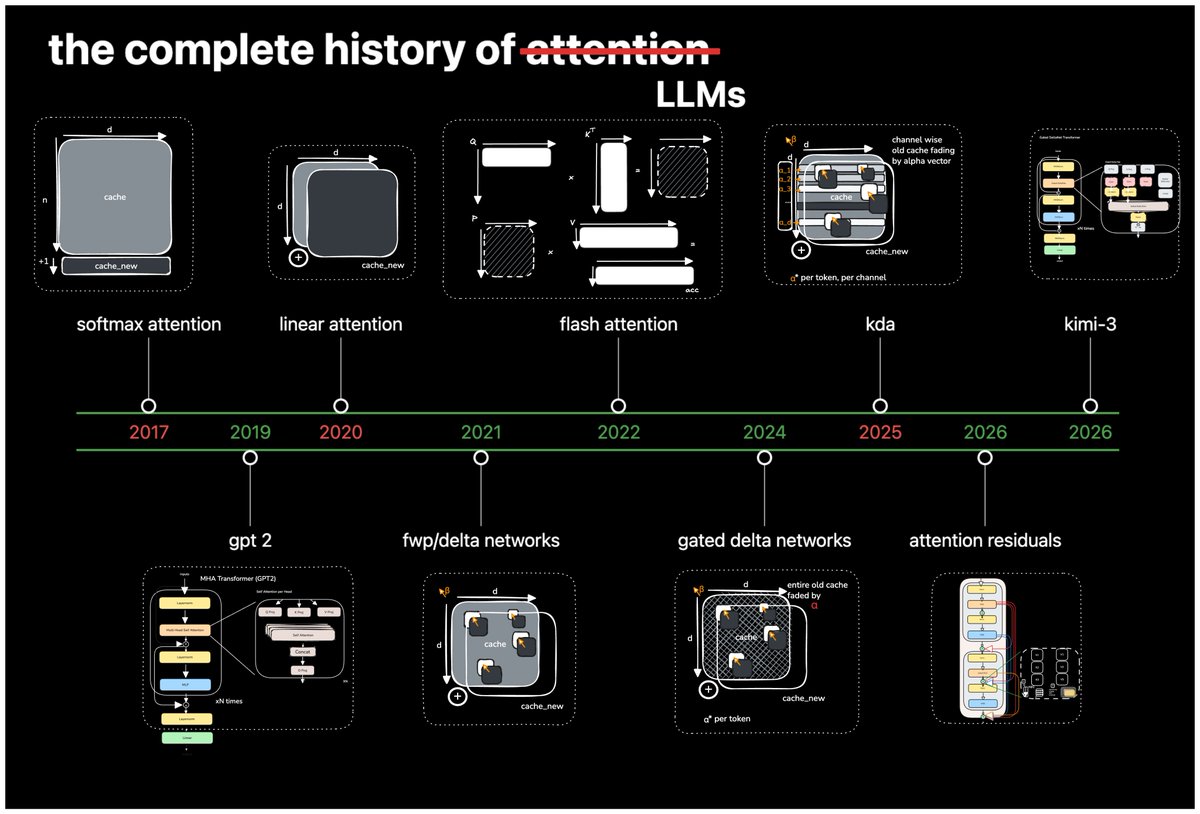
Twenty-two thousand five hundred and eighty. That’s how many GPT-2 (2019) models fit inside KimiK3 (2026). We scaled up by a factor of 22,580 in seven years. But is it just... scale?
Kimi-K3于2026年7月底正式发布,堪称规模最大的开源模型,它的参数规模是GPT-2的22,580倍。也就是说,在LLM出世以来,研究人员已经把它从小小的GPT-2 “养大” 了这么多。
它仅仅是变大了吗?
该博客围绕这个问题展开。回答是显而易见的:当然不只是一味地增多block,加入更多的layer。随着模型规模变大,处理的数据变多,任务更难,模型的架构也在变得复杂,越来越多巧妙的设计出现,用于处理复杂的信息流。
就像一个信息管理系统,当处理的数据越来越复杂的时候,内部的组织架构也要随着升级。
In this worklog, I’ll walk through how we got here and how much, or how little, has actually changed since then. We’ll trace the major architectural developments leading to KimiK3.
GPT-2
通过GPT2来介绍最基本的Attention架构,如果你已经很熟悉,可以跳过这一节!
GPT-2 is a decoder-only architecture:
为什么叫decoder-only架构呢?因为传统的Transformer架构长这样:
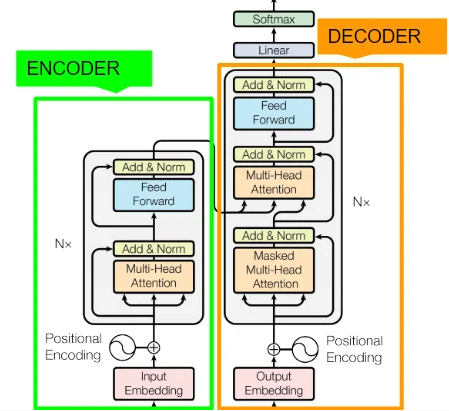
而GPT架构的大致代码如下,只保留了右边的Decoder,所以是Decoder Only :
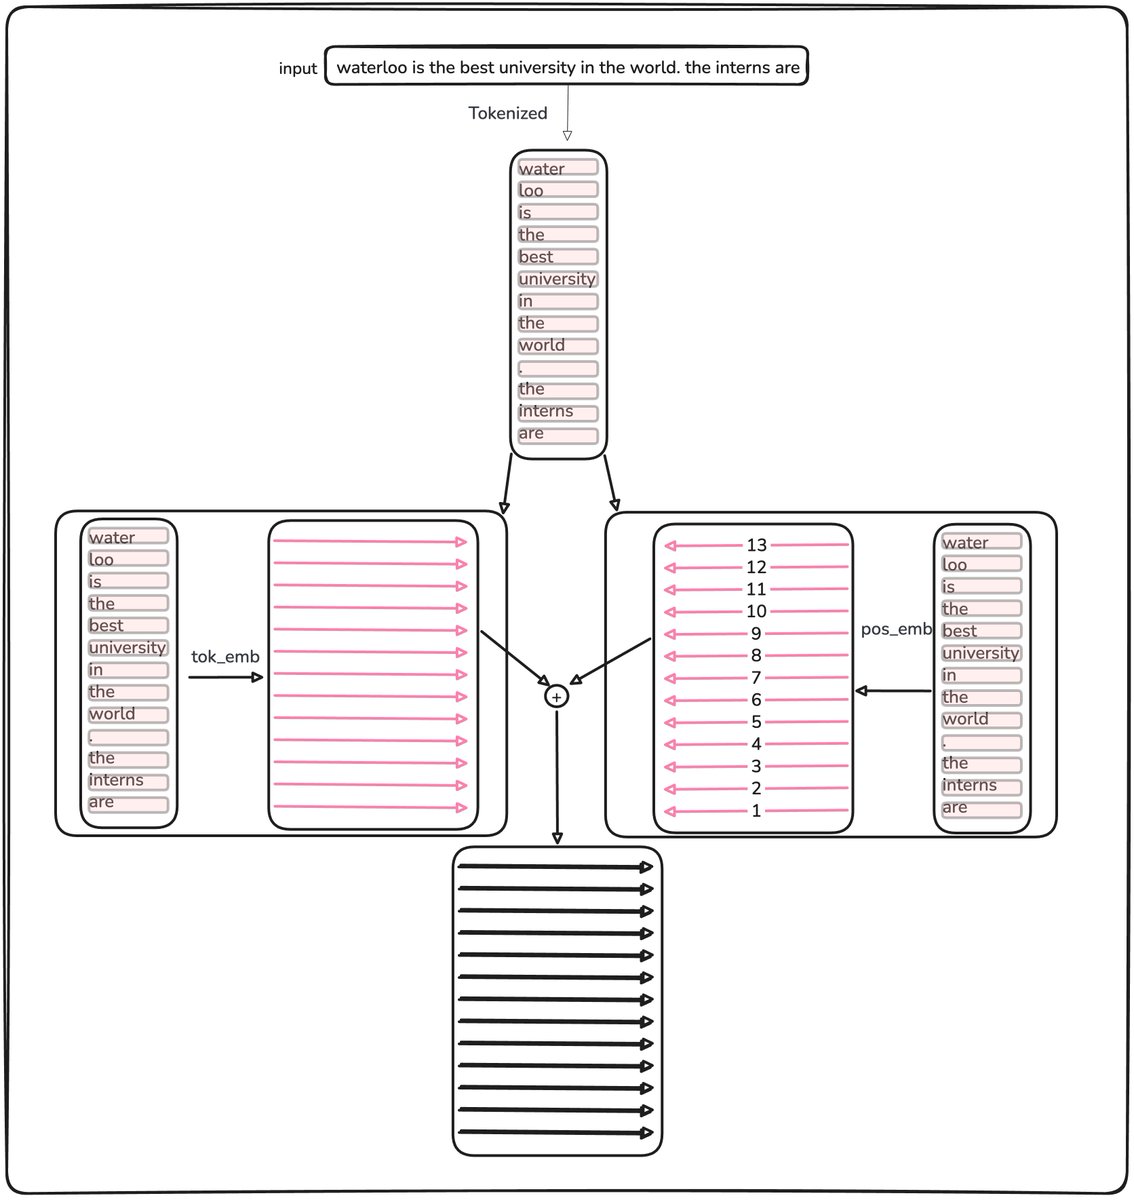
tok_emb = self.transformer.wte(idx) # token embeddings of shape (b, t, n_embd)
pos_emb = self.transformer.wpe(pos) # position embeddings of shape (t, n_embd)
x = self.transformer.drop(tok_emb + pos_emb)
for block in self.transformer.h:
    x = block(x)
x = self.transformer.ln_f(x)
logits = self.lm_head(x)
return logits
Decoder和Encoder部分的主要区别在于:
Decoder 的attention是 causal / masked self-attention,只能看到过去的,不能看到未来的:
        K
        A B C D
Q   A   ✓ × × ×
    B   ✓ ✓ × ×
    C   ✓ ✓ ✓ ×
    D   ✓ ✓ ✓ ✓
Encoder 一般是 bidirectional self-attention,每个 token 都可以看过去未来所有其它 token:
        K
        A B C D
Q   A   ✓ ✓ ✓ ✓
    B   ✓ ✓ ✓ ✓
    C   ✓ ✓ ✓ ✓
    D   ✓ ✓ ✓ ✓
有趣的是,在大语言模型的发展史上,出生于GPT之前的杰出架构Bert使用的是Encoder-only结构,与GPT相反。过了几年,GPT架构后来居上,成为生成式大语言模型的基础架构。本文不做具体的数学上的分析,可以大概这样理解:
Decoder-only 的信息流和“逐 token 生成文本”这个任务天然匹配,所以特别适合做生成式大模型;BERT 的 Encoder-only 则更适合“理解已有文本”,而不是连续生成。
The input receives token and positional embeddings:
Each transformer block, zoomed in, looks like this:
class Block(nn.Module):
    def __init__(self, config):
        super().__init__()
        self.ln_1 = LayerNorm(config.n_embd, bias=config.bias)
        self.attn = CausalSelfAttention(config)
        self.ln_2 = LayerNorm(config.n_embd, bias=config.bias)
        self.mlp = MLP(config)

    def forward(self, x):
        x = x + self.attn(self.ln_1(x))
        x = x + self.mlp(self.ln_2(x))
        return x
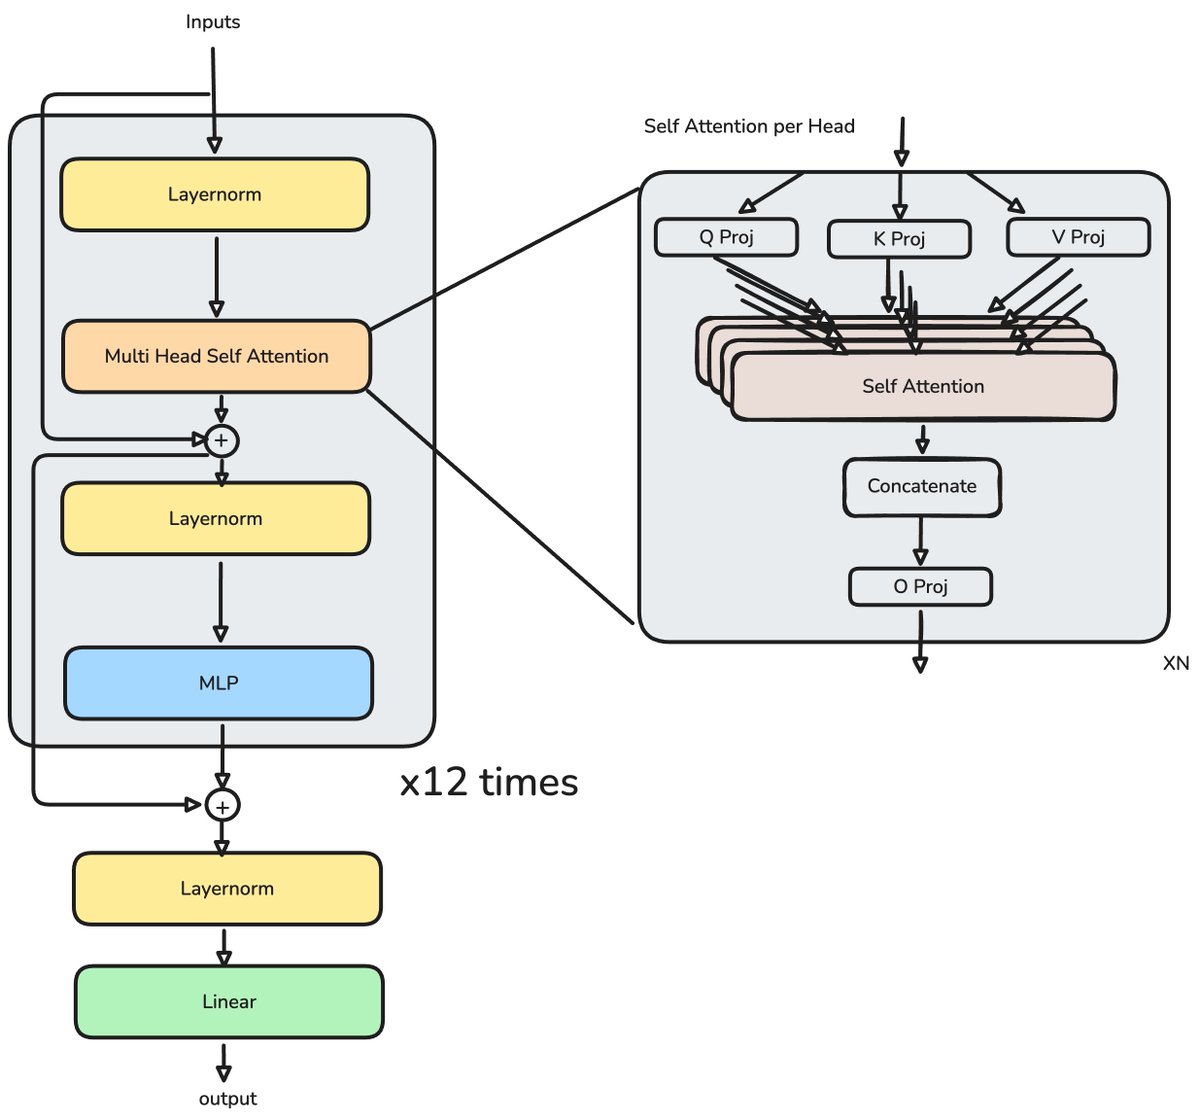
The attention process:
       B, T, C = x.size() # batch size, sequence length, embedding dimensionality (n_embd)

        # calculate query, key, values for all heads in batch and move head forward to be the batch dim (multi-head attention)
        q, k, v  = self.c_attn(x).split(self.n_embd, dim=2)
        k = k.view(B, T, self.n_head, C // self.n_head).transpose(1, 2) # (B, nh, T, hs)
        q = q.view(B, T, self.n_head, C // self.n_head).transpose(1, 2) # (B, nh, T, hs)
        v = v.view(B, T, self.n_head, C // self.n_head).transpose(1, 2) # (B, nh, T, hs)

        # manual implementation of attention
        att = (q @ k.transpose(-2, -1)) * (1.0 / math.sqrt(k.size(-1))) ## q和k相乘计算attention分数
        att = att.masked_fill(self.bias[:,:,:T,:T] == 0, float('-inf'))
        att = F.softmax(att, dim=-1)
        att = self.attn_dropout(att)
        y = att @ v # (B, nh, T, T) x (B, nh, T, hs) -> (B, nh, T, hs) attention分数和v相乘,表示对这个token的信息分配多少注意力
        # 拼接Multi-head的结果
        y = y.transpose(1, 2).contiguous().view(B, T, C) # re-assemble all head outputs side by side

        # output projection;Multi-head的结果通过一个线性层混合,形成整个 Multi-Head Attention 的最终输出。
        y = self.resid_dropout(self.c_proj(y))
        return y
大致总结下 attention 计算过程如下:
对于第 $i$ 个 token 在当前这一层的 hidden state $x_i$ (代码中简化为x):
- 计算Q, K,V 矩阵。
- 为多头注意力计算做准备:把大的 Q、K、V 张量拆成多个 head 对应的小矩阵。
- 计算attention分数矩阵;Softmax 后得到 attention weight 矩阵。
- 多头注意力的结果拼接起来,再通过一个线性层混合,做为最后的输出。
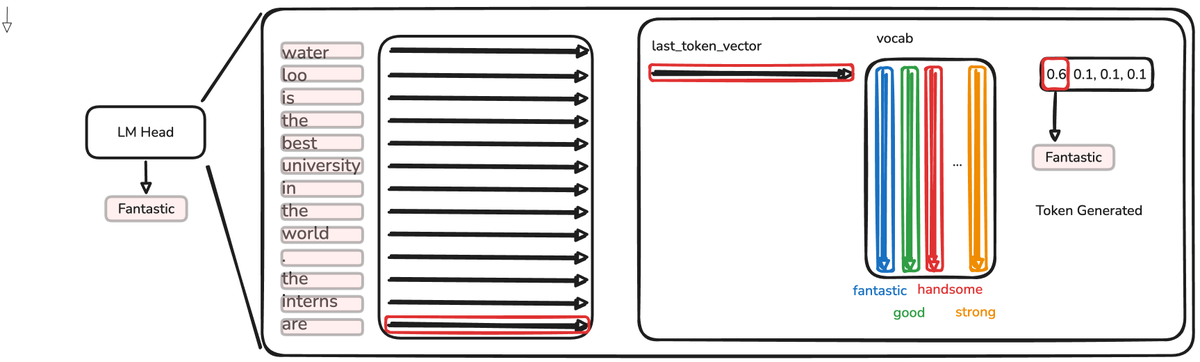
Once the final hidden-state matrix is produced, the language-model head maps it into vocabulary logits. During autoregressive decoding, only the logits at the final position are needed to select the next token.
生成式语言模型需要输出下一个词,它是根据概率来选择下一个词到底输出什么的,所以就出现上面提到的“the language-model head maps it into vocabulary logits”, 表示LLM head把每个位置的 hidden state 转换成“词表里每个 token 作为下一个 token 的未归一化分数”,然后由softmax转化为概率,选择对应概率最高的那个词。
This is an inefficiency of decoder-only generation: the model computes representations for every input position, but each decode step consumes only the final position’s logits. Without caching, much of that work would be repeated for the next token.
The KV cache comes from a straightforward observation: after appending the generated token to the input, the model would otherwise recompute projections for all previous tokens. Storing their key and value vectors avoids that redundant work.
为什么我们需要KV cache呢?因为每次在生成下一个词的时候,我们都利用了前面词的信息。
假设当前输入是:
I love machine
模型经过 12 层 Transformer 后,会得到 $h_1, h_2, h_3$, 也就是每个位置的 final hidden state:
I        → h1
love     → h2
machine  → h3
然后每个 hidden state theoretically 都可以经过 LM Head 得到 vocabulary logits:
h1 → logits1 P(x2∣x1)
h2 → logits2 P(x3∣x1,x2)
h3 → logits3 P(x4∣x1,x2,x3)
但现在是在做 generation,我们只需要预测下一个 token P(x4∣x1,x2,x3)
所以真正需要的只有 h3→logits3
比如生成:
learning
这就是所谓:
each decode step consumes only the final position's logits
但要注意是 只使用最后位置的 logits,不等于只使用最后 token 的信息。 因为 h3=f(x1,x2,x3),它已经通过 causal attention 读取了前面所有 token。
所以,每一步计算,都需要前面token的Q, K, V信息,随着计算步骤后移,需要的之前token的信息也就会越来越多。KV cache的作用就是使得,对于已经出现过的 token,它们的 K 和 V 不需要重新算。
比如对于:
I love machine
某一层 attention 已经计算出了$K_1,K_2,K_3$ 和 $V_1,V_2,V_3$ ,
然后生成:
learning
对于下一步,我们只需要计算新 token 的 $q_4,k_4,v_4$, 然后 $q_4$ 去和之前存下来的$K_1,K_2,K_3$ 以及 $K_4$ 计算 attention。
That storage is the KV cache. It retains vectors for the previous N-1 tokens and can become large enough to create a memory-bandwidth bottleneck.
值得注意的是,模型的每一层都需要有一份KV cache,因为每个token在某一层的Q, K, V都是它的潜在表示经过该层的W矩阵得到的,每一层的W矩阵都不一样!所以每一层的Q,K,V也都不一样。
Overall, with about 50k possible tokens, 12 blocks, 12 heads, and an embedding dimension of 768, our baseline model is about 124M parameters.
vocab_size: int = 50304 # GPT-2 vocab_size of 50257, padded up to nearest multiple of 64 for efficiency
n_layer: int = 12
n_head: int = 12
n_embd: int = 768

At 2.8 trillion parameters, one KimiK3 model contains roughly as many parameters as 22,580 GPT-2 models.
所以,随着context 越长 ,KV cache 就要越大。
Linear Attention
Softmax attention applies its nonlinearity after the q·k product, coupling every query to every key. Linear attention instead applies a feature map, such as ELU+1, to q and k separately. This makes the product re-associable, so the growing set of K and V vectors can be folded into a fixed D×D state.
这一节介绍Linear Attention。在前面我们看到的简易代码中,attention是这样计算的,这是softmax attention:
att = (q @ k.transpose(-2, -1)) * (1.0 / math.sqrt(k.size(-1))) ## q和k相乘计算attention分数
        att = att.masked_fill(self.bias[:,:,:T,:T] == 0, float('-inf'))
        att = F.softmax(att, dim=-1)
        att = self.attn_dropout(att)
        y = att @ v
先算$qk$,然后对qk做softmax,再和v相乘。
我们看下这样计算 $(QK^⊤)V$ 的复杂度:
$Q, K ∈ N × d$, 那么 $QK^⊤∈N×N$,
N 表示数据量,一般来说,训练和推理的数据量都是很大的,所以$N^2$是一个不容忽视的复杂度。
由于同样, $V ∈ N × d$, 那么可以看出,如果是$Q(K^⊤V)$ :
$K^⊤V∈d×d$, 这时候主要复杂度来自$d^2$,相比数据量,数据的维度往往没有那么大,这时候计算复杂度就下降很多了。
但是softmax attention对qk做softmax,导致这样的矩阵结合律无法使用。
同时,Softmax Attention 在生成第 t 个 token 时保存 $K_{1:t},V_{1:t}$,KV cache 大小随着 sequence length 增长。所以我们希望在计算和存储上进行优化。
Linear Attention怎么做的呢?就像作者下面说的:
replace the exponential used by softmax with ELU+1 applied separately to q and k before they interact. Both approaches normalize the resulting scores
Linear Attention 的核心思想就是:
能不能把原本合并的 attention kernel 写成两个独立 feature map 的内积?
也就是把 $\exp(q^\top k)$ 换成 $\phi(q)^\top\phi(k)$
例如: ϕ(x)=ELU(x)+1,
如此一来,q和k就分开了,我们可以使用矩阵乘法的结合律来实现计算效率的提升了。
所以,对一个 query $q_i$, 它和其它第j个token通过k、v的attention计算就从:
$$o_i = \sum_{j \le i} \frac{\exp(q_i^\top k_j)}{\sum_{l \le i} \exp(q_i^\top k_l)} v_j$$
变成了
$$o_i = \frac{\sum_j \phi(q_i)^\top \phi(k_j) v_j}{\sum_j \phi(q_i)^\top \phi(k_j)}$$
$\phi(k_j) v_j$ 可以通过结合率提前一起计算了。
再进一步观察,我们发现,式子可以把 $\phi(q_i)^\top$ 作为一个常数提出来,而${\sum_j \phi(k_j) v_j}$ 是一个整体!
于是,我们定义: $\boxed{ S_i=\sum_{j\le i}\phi(k_j)v_j^\top }$
而分母也可以写成 $ϕ(qi)^⊤(j∑ϕ(kj))$,
于是我们定义另一个 state:$\boxed{ z_i=\sum_{j\le i}\phi(k_j) }$
之后,我们不需要KV cache了,只需要存储一个S和一个z,并且每一步都更新它们,就如代码:
k = F.elu(k) + 1
q = F.elu(q) + 1

S, z = cache if cache is not None else (0.0, 0.0)
S = S + k @ v
z = z + k

o = q @ S
denom = q @ z

o_scaled = o / denom
生成下一个 token的时候直接更新状态 $S_{t+1} = S_t+\phi(k_{t+1})v_{t+1}^\top$
然后 $o_{t+1} = \frac{ \phi(q_{t+1})^\top S_{t+1} }{ \phi(q_{t+1})^\top z_{t+1} }$
不需要再扫描 K1,…,Kt。
所以Linear Attention就像直接维护了一个历史状态的summary,新的q来了直接和这个summary相乘得到信息。
S0
↓
(k1,v1)
↓
S1
↓
(k2,v2)
↓
S2
↓
...
SN
值得注意的是,“ linear attention is a less expressive approximation of the softmax kernel ”,就是说Linear Attention 比 Softmax Attention 表达能力弱。这是显而易见的,毕竟Linear Attention 把所有信息存在了一个过去的历史状态里面,是一个summary,不记录各种具体的细节。
下面这一段原作者表达了一点困话,我做了简单的澄清:
The paper’s $O(N²)$ framing threw me off. It's not true that "the cost per time-step for transformers scales with the square of the current sequence length". That's what Flash Attention fixes... then I saw that it was released in 2020.
FlashAttention 并没有把标准 Softmax Attention 的数学计算量从 $O(N^2)$ 变成 $O(N)$。它仍然计算精确的 softmax(QK⊤)V ,它主要解决的是 GPU 显存读写和中间矩阵存储问题。
普通实现显式生成 $QK^\top\in\mathbb R^{N\times N}$
然后把这个大矩阵写入显存,再读取回来做 softmax 和乘 V。
FlashAttention 通过分块计算:
- 不把完整 N×N 注意力矩阵写入 HBM;
- 在 GPU SRAM 中分块计算;
- 在线维护 softmax 的归一化量;
- 显著减少显存访问和中间内存。
At the time, training commonly materialized the full N×N attention matrix, FlashAttention did not exist, and reference autoregressive implementations often recomputed the token history without a KV cache.
def forward(self, x, mask=None, past_kv=None):
  # x is b,t,d
  b,t,d=x.shape
  d_head=d//self.num_heads
  h=self.num_heads
  qkv=self.qkv_proj(x)

  q=qkv[:, :, :d].view(b,t,h,d_head).transpose(1,2)
  k=qkv[:, :, d:2*d].view(b,t,h,d_head).transpose(1,2)
  v=qkv[:, :, 2*d:].view(b,t,h,d_head).transpose(1,2)

  # at prefill, q,k,v have shapes b,h,t,d
  # at decode, shape is b, h, 1, d
  # so i cat at the t dimension, dim(2)

  if past_kv is not None:
    k_past=past_kv[0]
    v_past=past_kv[1]
    k=torch.cat((k_past, k), dim=2)
    v=torch.cat((v_past, v), dim=2)

  scores=(q@k.transpose(-1,-2))/math.sqrt(d_head)
  if past_kv is None: #we're in prefill and need to mask
    causal_mask=torch.ones(t,t,dtype=bool, device=q.device)
    causal_mask=torch.triu(causal_mask, diagonal=1)
    scores=scores.masked_fill(causal_mask, float('-inf'))

  if mask is not None:
    scores=scores.masked_fill(~mask, float('-inf'))

  #get attn (bhtt x bhtd)
  attn=scores.softmax(-1)#bhtt
  o=attn@v #bhtd
  o=o.transpose(1,2).contiguous().view(b,t,d)  #b,t,d

  # use x to get qkv
  o_proj=self.o_proj(o)
  past_kv=(k, v)
  return o_proj, past_kv

The same process is easier to see visually. Each decode step performs two ND reads and two 1D writes to HBM, while the KV cache grows linearly, in O(N), with the sequence length.
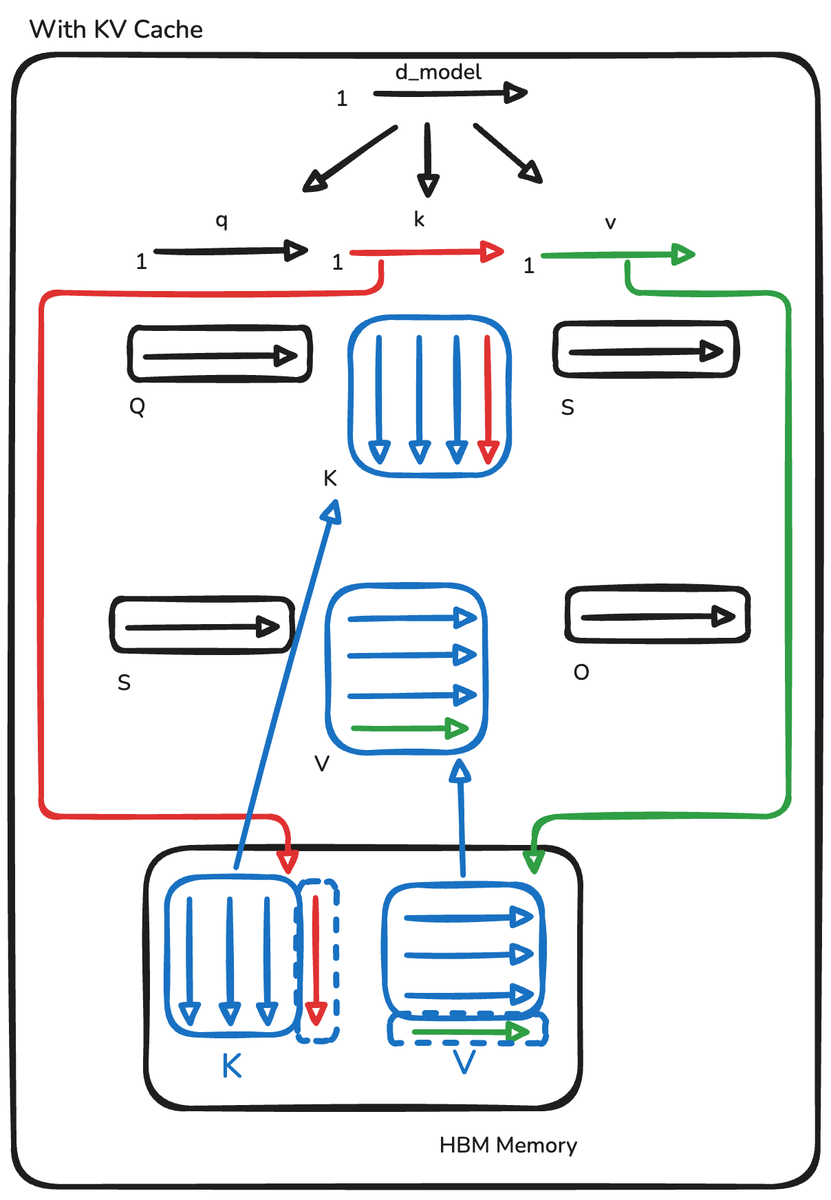
Notice the excessive reads and writes, which this paper replaces with:
def forward(self, x, mask=None, cache=None):
  # x is b,t,d
  b,t,d=x.shape
  d_head=d//self.num_heads
  h=self.num_heads
  qkv=self.qkv_proj(x)

  q=qkv[:, :, :d].view(b,t,h,d_head).transpose(1,2)
  k=qkv[:, :, d:2*d].view(b,t,h,d_head).transpose(1,2)
  v=qkv[:, :, 2*d:].view(b,t,h,d_head).transpose(1,2)

  k=F.elu(k)+1
  k=k.transpose(-1,-2)
  q=F.elu(q)+1

  S,z=cache if cache is not None else (0.0, 0.0)
  S=S+k@v
  z=z+k

 o=q@S #bhtd
 denom=q@z
 o_scaled=o/denom
 o_scaled=o_scaled.transpose(1,2).contiguous().view(b,t,d)
 o_proj=self.o_proj(o_scaled)
 cache=(S,z)

 return o_proj, cache

There is a trade-off.
Here, we replace the exponential used by softmax with ELU+1 applied separately to q and k before they interact. Both approaches normalize the resulting scores, but the feature map used by linear attention is a less expressive approximation of the softmax kernel. That approximation can reduce fidelity, although the practical accuracy loss depends on the architecture and workload.
Notice that we still divide by the sum of qk, which is omitted from the diagram for simplicity. At a high level, attention consists of three steps:
Make the qk scores non-negative. Linear attention uses ELU+1, while softmax uses exponentiation.
Divide by the sum.
Compute the weighted average of the values.
This preserves the basic attention contract, but uses a less expressive feature map to make the QK scores non-negative.
DeltaNet (Fast Weight Programmers)
A finite cache must overwrite or combine with information already stored. The state from token i-1 does not receive its own slot; it is added to the same D by D matrix. New queries can therefore no longer retrieve a perfectly isolated representation of each earlier token.
That addition is also the source of the efficiency gain. Updating the cache additively rather than by concatenation prevents it from growing in O(N), but the same operation causes information to interfere. DeltaNet addresses this loss of recoverability.
Linear Attention解决了Softmax Attention的问题,但是也带来了新的问题,比如单纯的修改历史累计状态无法对历史记忆做细粒度的控制。所以之后有一系列的工作在不断改进这个问题。DeltaNet 通过类似误差修正的写入规则,让同一个 Key 对应的旧值可以被新值覆盖,而不是一直叠加。
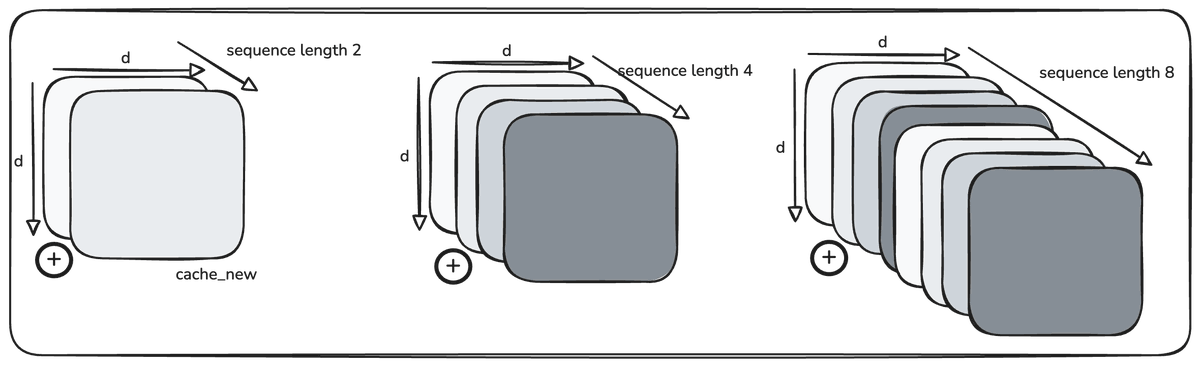
Eloquently put by Schlag’s paper (Fast Weight Programmers): “when the sequence length exceeds storage capacity, the model may end up in an overcapacity regime. To properly operate under such a regime, the model should learn to dynamically interact with the memory contents and selectively decide which key-value associations to keep and which ones to delete. The purely additive instruction may be inappropriate for this purpose…. endlessly adding new associations to a memory of finite size, as in Eq. 17, inevitably will reach a limit.“
The regime that makes linear attention attractive, where N is much larger than D, also exposes its main limitation. Once the state exceeds its effective capacity, associations begin to interfere because the update is additive and nothing leaves the cache.
def forward(self, x, mask=None, cache=None):
  # x is b,t,d
  b,t,d=x.shape
  d_head=d//self.num_heads
  h=self.num_heads
  qkv=self.qkv_proj(x)

  q=qkv[:, :, :d].view(b,t,h,d_head).transpose(1,2)
  k=qkv[:, :, d:2*d].view(b,t,h,d_head).transpose(1,2)
  v=qkv[:, :, 2*d:].view(b,t,h,d_head).transpose(1,2)

  q = F.normalize(F.silu(q), dim=-1)
  k = F.normalize(F.silu(k), dim=-1)
  beta = torch.sigmoid(self.w_beta(x)).view(b, 1, t, 1)
  # new: per-token write strength

  S = cache if cache is not None else 0.0

  v_old = k @ S # read the board at this key
  u = beta * (v - v_old) # the delta: only what's actually new
  S = S + k.transpose(-1, -2) @ u # same outer-product write as before

  o = q @ S # read, no denominator
  o = o.transpose(1, 2).contiguous().view(b, t, d)
  return self.o_proj(o), S

A visual example makes this easier to follow.
DeltaNet 不直接写入新 Value,
而是先问:
当前这个 Key 已经能从记忆中读出什么?
即$v_old=kS$
然后计算目标值与当前值之间的差:
$Δv=v_new−v_old$
最后只写入这个差值:$S_{\text{new}} = S_{\text{old}} + k^\top\Delta v$
也就是:$S_{\text{new}} = S_{\text{old}} + k^\top (v_{\text{new}}-v_{\text{old}})$
这就是所谓的 delta update:只写入误差或增量,而不是重复写入完整内容。
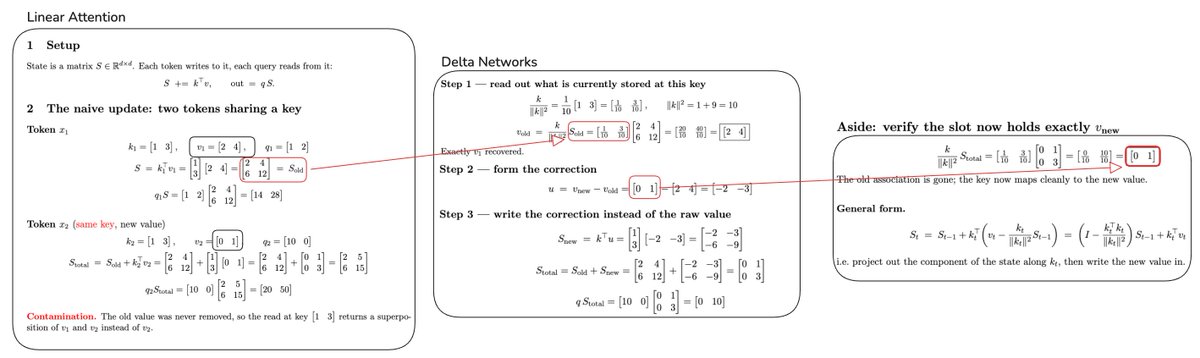
Take a single association written as S = k.T @ v. If read back with the same key and you get k @ (k.T @ v), which is (k @ k.T) v, which is the squared norm of k times v. So read returns scaled by key's squared norm, and if normalize k to unit length, or just divide result by norm, get v back exactly.
Q is also a learned pointer. Wq and Wk read the same residual stream, and the query for a fact points at the key direction that fact was written into. The update first asks what information the current key retrieves from the cache. It subtracts that existing information from the value we want to store, multiplies the key by the difference, and adds the result back. Old information is removed and new information is written in its place.
上图举了一个具体的例子:
原有的关联是:$k=[1,3]$ ,$v_{\text{old}}=[2,4]$
状态为:$S_{\text{old}} = \begin{bmatrix} 2&4\ 6&12 \end{bmatrix}$
现在希望同一个 Key 存储新值:$v_{\text{new}}=[0,1]$
第一步,使用归一化读取地址:$\frac{k}{|k|^2} = \left[\frac{1}{10},\frac{3}{10}\right]$ , 得到:$v_{\text{old}} = \frac{k}{|k|^2}S_{\text{old}} = [2,4]$
第二步,计算修正量,$u = v_{\text{new}}-v_{\text{old}} , u=[0,1]−[2,4]=[−2,−3]$
第三步, 写入修正量, $S_{\text{correction}} = k^\top u =\begin{bmatrix} 1\3 \end{bmatrix} [-2,-3] = \begin{bmatrix} -2&-3\ -6&-9 \end{bmatrix}$
加到原状态:$S_{\text{total}} = S_{\text{old}}+S_{\text{correction}} =\begin{bmatrix} 2&4\ 6&12 \end{bmatrix} + \begin{bmatrix} -2&-3\ -6&-9 \end{bmatrix} = \begin{bmatrix} 0&1\ 0&3 \end{bmatrix}$
再读取的时候,读到的就是新的值:$\frac{k}{|k|^2}S_{\text{total}} = [0,1] = v_{\text{new}}$,
完整的DeltaNet公式是:$v_{old}=k_tS_{t−1} ,S_t=S_{t−1}+β_tk_t^⊤(v_t−v_{old})$ ,
其中Beta是一个控制门,控制当前 token 的信息到底应该多大程度写进记忆,
- $β=1$:完全覆盖旧值;
- $β=0$:不更新;
- $0<β<1$:在旧值和新值之间平滑更新。
⚠️ 关于$v_{old}=k_tS_{t−1}$ 的理解:
由于k是被归一化了的,所以当S里面只有一个元素的时候,用同一个k写入的状态值可以继续被k读取,如下:
$S=k^⊤v$ , $kS=k(k^⊤v)= v$
但是S里面逐渐地就不只有一个元素了,所以 $kS$ 是当前内存 $S$ 在 Key $k$ 这个地址上“现在能够读出来的内容”。
DeltaNet (Parallelizing Linear Transformers with Delta Rule)
This is the most difficult section of the post. It took me about seven hours to develop a working understanding of it, so I will build the explanation from the implementation.
In short, DeltaNet implements a first-order linear recurrence with generalized Householder transition matrices, enabling chunk-wise parallel forward passes for hardware-efficient linear-time training.
这一部分是关于如何提升DeltaNet的计算效率的:用一个“当前状态只依赖前一状态”的线性递归来维护记忆。每一步都通过一个类似 Householder 矩阵的变换,先删除旧信息,再写入新信息。由于这种递归可以被数学重写,模型不必在 prefill 阶段逐 token 串行运行,而可以把序列分块,在每个块内使用 GPU 高效的大矩阵运算,同时保持关于序列长度的线性复杂度。
It splits the inputs and outputs into several chunks of size C, and computes outputs for each chunk based on the final state of the previous chunk and the query key value blocks of the current chunk.
它把序列切成若干个长度为 C 的块。处理一个块时,以前所有块的信息都由上一个块结束时的固定状态 S 表示;当前块内部的信息则由当前块的 Q,K,V 矩阵共同计算。当前块处理完成后,产生新的最终状态,再传给下一个块。
The practical problem is prefill. A direct implementation of the Delta rule over a sequence of T tokens would look like this:
DeltaNet的效率瓶颈在哪里呢?主要出现在像Prefill这样的任务里面。首先Prefill是大语言模型推理的第一个阶段,在这个阶段里,模型会一次性处理整段 prompt,为每个位置计算隐藏状态,并建立后续生成所需要的缓存。
例如用户输入 The capital of France is ,这 5 个 token 是已经给定的。模型会一次性处理整段 prompt,为每个位置计算隐藏状态,并建立后续生成所需要的缓存。
Prefill 完成后,模型开始生成 Paris ,然后再生成下一个 token。这就是第二个阶段,Decode 阶段,通常一次只处理一个新 token,并利用之前建立的缓存。
对于 DeltaNet,单步 decode 很自然,因为它本来就是递归状态更新:
$$S_{t−1}→S_t$$
而真正困难的是DeltaNet 在 prefill 阶段:
S = torch.zeros(b, h, dh, dh) if cache is None else cache
outs = []
for i in range(t):
    k_i = k[:, :, i:i+1]
    v_i = v[:, :, i:i+1]
    b_i = beta[:, :, i:i+1]
    v_old = k_i @ S
    u_i  = b_i * (v_i - v_old)
    S = S + k_i.transpose(-1, -2) @ u_i # write
    outs.append(q[:, :, i:i+1] @ S)
o = torch.cat(outs, dim=2)
Unlike standard attention, this formulation requires a correction at every key vector, so the path to a parallel matrix multiplication is not immediately obvious.
这里每个 token 都依赖前一个 token 更新后的状态:
$$S_i \ depends \ on \ S_{i−1}$$
所以不能简单地把所有 token 同时计算。但是如果 prompt 有几千个 token,一个 token 一个 token 串行更新,GPU 利用率会很低。理论上 FLOPs 可能仍然是线性的,但 GPU 不擅长执行成千上万个很小、严格串行的矩阵运算。它更擅长一次计算较大的矩阵乘法。
因此问题是:
如何保持 Delta Rule 的精确结果,同时减少 token 级串行依赖?
Even without the Delta rule, a direct linear-attention prefill remains sequential:
容易想到的是“分块”。具体如何分呢?先看看不带Delta的Linear Attention,其实本身也是线性难以并行的:
S = torch.zeros(b, h, dh, dh) if cache is None else cache
outs = []
for i in range(t):
    q = q[:, :, i:i+1]
    k = k[:, :, i:i+1]
    v = v[:, :, i:i+1]

    S=S_old+k@v
	  o=q@S #bhtd
	  o=self.norm(o)
    o=o.transpose(1, 2).contiguous().view(b, t, d)

    out=self.o_proj(o)
    cache=S
    outs.append(out)

o = torch.cat(outs, dim=2)
A chunked formulation provides a more efficient approach. The mechanics are easier to understand through an example:
Linear Attention的分块如下图所示,从左到右看
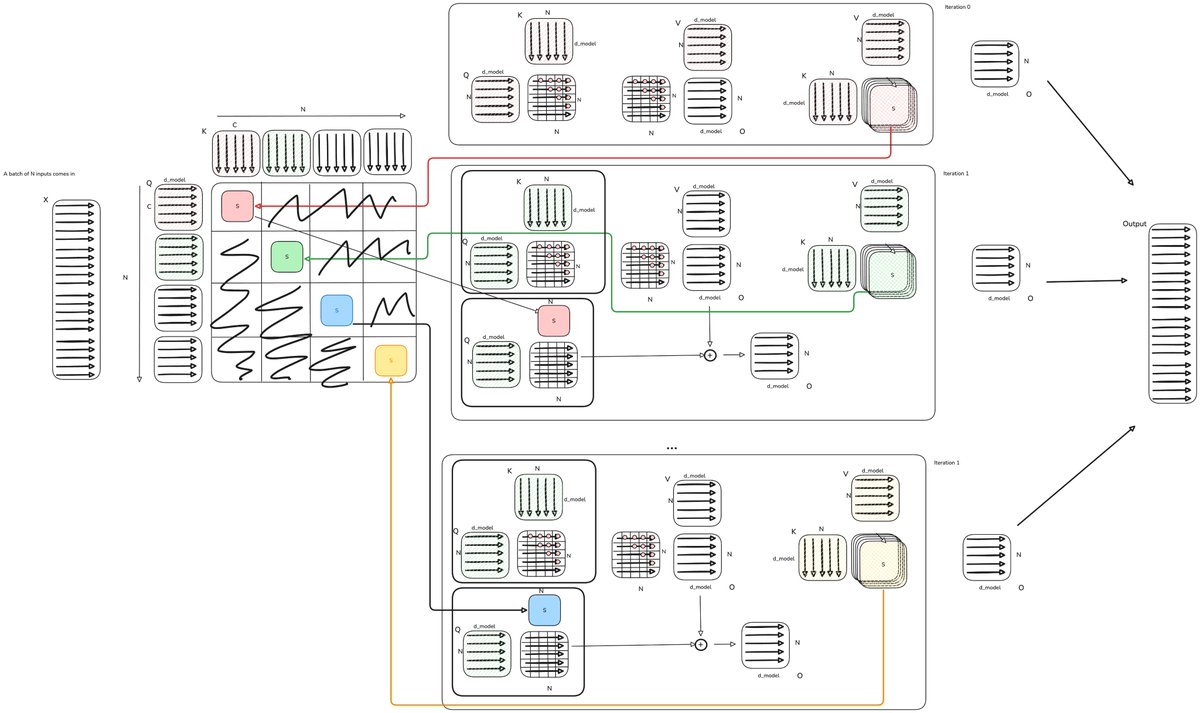
Setting C=N recovers standard O(N^2) attention, while C=1 gives regular linear attention.
将一个长度为 L 的序列分成若干块,每块包含 C 个 token。$C=N$ 会退化成完整 attention, 而$C=1$ 就是是普通线性 attention
Intermediate values we interpolate between trade additional within-chunk work for better hardware utilization. In practice, C is often 64 or 128 because tensor-core instructions operate efficiently at that granularity; UMMA is one example.
这段话可以这么理解:
| C的值 | 块内计算 | 状态计算 | 特点 |
|---|---|---|---|
| $1$ | 几乎没有 | 每 token 更新 | FLOPs 最少,但矩阵太小 |
| $64/128$ | 小规模普通 attention | 块间状态 | GPU 通常最有效率 |
| $N$ | 完整 attention | 状态基本无用 | $O(N^2)$ |
| 因此它在两个极端之间进行插值: | |||
| $$Linear \ attention⟷Full\ attention$$ |
接下来单独拆解上图:
假设序列长度为 $N$,将它切成若干个长度为 $C$ 的块:
$$(Q_0, K_0, V_0), (Q_1, K_1, V_1), \dots$$
每个块都有:
$$Q_i, K_i, V_i \in \mathbb{R}^{C \times d}$$
并维护一个状态矩阵:
$$S_i \in \mathbb{R}^{d \times d}$$
在处理第 $i$ 个块之前,状态保存所有更早块的信息 (Linear Attention核心思想):
$$S_{i-1} = \sum_{j<i} K_j^\top V_j$$
第 $i$ 个块的输出分成两部分:
$$O_i = \underbrace{Q_i S_{i-1}}{\text{过去所有块}} + \underbrace{\text{tril}(Q_i K_i^\top) V_i}{\text{当前块内部}}$$
然后更新状态:
$$S_i = S_{i-1} + K_i^\top V_i$$
这是核心的点,请记住哦。
然后我们看向左边图中那个红色的 $s$ 块,这是计算产生的第一个块。由于在这之前没有历史状态产生,所以因此第一个块只执行块内普通 attention,也就是传统的 $QKV$ 计算,如图中间三块最上方那块所示的计算过程。往左红色箭头表示存储结果为$S_0$ 。
然后是左边图中绿色的 $s$ 块,作为第二个块,有两个输出来源:
$$O_1 = \underbrace{Q_1 S_0}{\text{读取第一个块}} + \underbrace{\text{tril}(Q_1 K_1^\top) V_1}{\text{第二块内部}}$$
图中间部分第二个块有个加号,表示把这两部分相加。
随后往左绿色箭头表示存储结果为 $S_1$ :
$$S_1 = S_0 + K_1^\top V_1$$
所以状态中已经包含第一个块和第二个块。
图中间部分的第三个块表示第四个黄色状态 $S_3$ 的计算,可以看到和第二个块的逻辑是一样的。
$$O_3 = Q_3 S_2 + \text{tril}(Q_3 K_3^\top) V_3$$
然后:
$$S_3 = S_2 + K_3^\top V_3$$
所以虽然前面有三个状态,但是当前块只需要一次:
$$Q_3 S_2$$
就能读取前面所有块的信息。
The intermediate tiles are folded into S as part of the state update:
![[from-gpt2-to-kimi3-11.jpg]]
S = torch.zeros(b, h, dh, dh) if cache is None else cache
outs = []
for i in range(t//C):
    q_c = q[:, :, i*C:(i+1)*C]
    k_c = k[:, :, i*C:(i+1)*C]
    v_c = v[:, :, i*C:(i+1)*C]

	  o_prev=q_c@S #this is everything up to this block

	  attn=(q_c@k_c.transpose(-1,-2)).tril() #masked attention
	  o_curr=attn@v_c

		o=o_prev+o_curr

    S_new=k_c.transpose(-1,-2)@v_c #recurrent attention
    S=S+S_new
    outs.append(o)

o = torch.cat(outs, dim=2)
Within a block, we do (qkᵀ)v. This is score first, the normal attention order with masking. Across blocks, we follow (kᵀv)q, so we’re doing recurrent order, state first. Attention grows in O(N²) and this does not. Inside a block I do real attention (the masked QKᵀ times V), and across blocks I fold everything into the state and read it back with one matmul.
块内:先算 token 与 token 的注意力分数,这个过程显式计算 token-to-token 的 $$QK^\top $$分数矩阵(score first),并施加因果 mask,最后再乘以V,是一个比较传统的attention计算。
块间:还记得每个块的输出是这样的吗:
$$O_i = \underbrace{Q_i S_{i-1}}{\text{过去所有块}} + \underbrace{\text{tril}(Q_i K_i^\top) V_i}{\text{当前块内部}}$$
第一个部分需要用到历史状态来计算,所以是state first。
So the cost splits in two. There's a fixed piece, 2Ld², which is the state work and doesn't care about C at all. And there's a growing piece, 2LCd, which is the score matrices sitting on the diagonal. Full attention is just the case where C equals L, and then that second term becomes 2L²d, quadratic. So the smaller I make C, the fewer FLOPs I do.
然后看下这种分块方式的时间复杂度:
令总序列长度为 $L$,那么共有 $\frac{L}{C}$ 个块。
cost的第一部分来自状态的计算:
每个块需要两次类似的矩阵乘法:$Q_i S$ 以及 $K_i^\top V_i$ ,每次约为$C d^2$(矩阵乘法 $(C×d)(d×d)$ 的计算量是 $C×d×d$, 而输出矩阵有 $C\times d$ 个元素。每一个输出元素需要经过$d$ 次乘法和 $d−1$ 次加法。复杂度 $O(d)$,总复杂度就是$C d^2$。)。两个操作、所有块合计:
$$2 \times \frac{L}{C} \times C d^2 = 2 L d^2$$
这一项与 $C$ 无关,所以是 ${2 L d^2}$
cost的第二部分来自块内attention计算:
每个块计算 $Q_i K_i^\top$,成本约 $C^2 d$,再计算$A_i V_i$, 也是 $C^2 d$。每块合计$2 C^2 d$。
所有块 $\frac{L}{C} \times 2 C^2 d = 2 L C d$
因此总成本:${2 L d^2 + 2 L C d}$。
可以看到当 $C = L$的时候,$2 L d^2 + 2 L^2 d$,出现标准 attention 的二次项,$O(L^2 d)$。
当 $C = 1$的时候,$2 L d^2 + 2 L d$,相对于序列长度 $L$ 是线性的 $O(L d^2)$。
C=1 is the cheapest option in pure FLOP terms, but not necessarily in wall-clock time. A GPU can complete more arithmetic faster when the work maps efficiently onto its matrix-multiply hardware.
虽然 $C=1$ 的时候总工作量(浮点计算数)不大,但是由于GPU太空闲了,导致计算速度不够快。
而 $C=64$ 或 128 往往更容易被切分为适合硬件的 tile,因此 Tensor Core 利用率更高。
[!NOTE]
The next step is to extend the same approach to DeltaNet.
前面都是在说Linear Attention要如何分块,现在来看看在Linear Attention上改进的DeltaNet要如何工作吧。
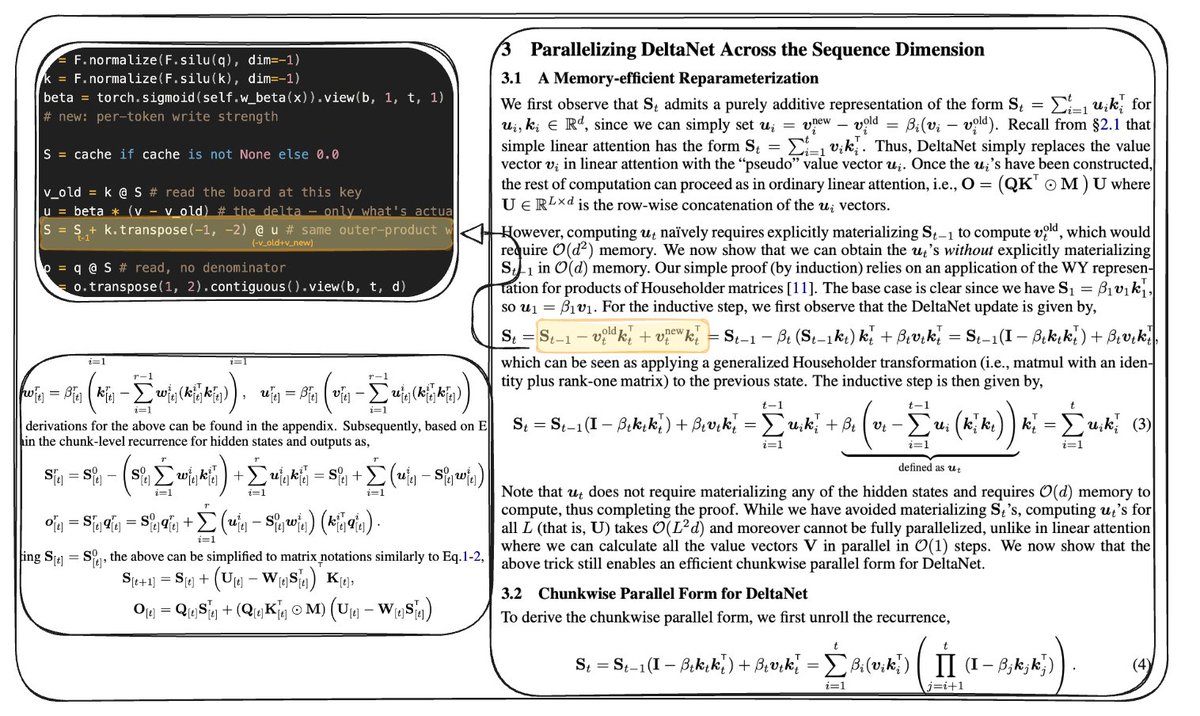
The underlying issue is simple: the chunking method used for purely additive attention does not directly apply to the delta updates:
v_old = k_i @ S
u_i  = b_i * (v_i - v_old)
We need every single state in order to compute the information that needs to be subtracted out.
普通线性注意力可以很容易地把每个 chunk 压缩成一个独立的增量 $K\top \ V$,但 DeltaNet 的更新量依赖“当前状态里已经存了什么”,所以不能直接套用同样的分块方法。
We can't parallelize it the same way without some mathematical re-parameterization. The authors therefore rewrite the delta updates from:
u=v_new-v_old
S_t= S_(t-1)+K.T@u
o=q@S_T
Here, a sequential loop computes one delta per iteration. The reparameterized form is:
S_t = S_{t-1}(I − β_t k_t k_tᵀ)  +  β_t v_t k_tᵀ
o_t = S_t q_t
首先我们做个变换,把delta更新改写成状态转移。
从 $u_t = \beta_t(v_t - k_t S_{t-1})$ 和 $S_t = S_{t-1} + k_t^\top u_t$,代入得到 $S_t = S_{t-1} + \beta_t k_t^\top v_t - \beta_t k_t^\top k_t S_{t-1}$
整理为 ${S_t = (I - \beta_t k_t^\top k_t) S_{t-1} + \beta_t k_t^\top v_t}$
这表示每个 token 对状态实施一个仿射变换,$S_t = A_t S_{t-1} + B_t$
其中,$A_t = I - \beta_t k_t^\top k_t$,$B_t = \beta_t k_t^\top v_t$
$A_t$ 是“单位矩阵减去一个秩一矩阵”,所以论文称它与 generalized Householder transformation 有关。(generalized Householder transformation可以理解为,用一个非常简单的秩一矩阵,只修改向量在某个特定方向上的分量,而保持其他正交方向基本不变。)
This formulation allows the chunked code to compute all C deltas at once:
def chunk_delta_rule_forward(Q, K, V, beta, C):
		# L: sequence length, d: head dimension
		L, d = Q.shape
		# chunking
		Q, K, V = map(lambda x: x.reshape(-1,C,d), [Q, K, V])
		beta = beta.reshape(-1, C)
		K_beta = K * beta.unsqueeze(-1)
		V_beta = V * beta.unsqueeze(-1)

		# compute eq. 10 with vectorized forward substitution for fast inverse
		T = -(K_beta @ K.t()).tril(-1)
		for i in range(1, C):
				T[i, :i] = T[i, :i] + (T[i, :, None] * T[:, :i]).sum(-2)

		T += torch.eye(C)
		W = T @ K_beta
		U = T @ V_beta

		# chunkwise parallel. Eq. 8-9
		S = torch.zeros(d, d)
		O = torch.empty_like(V)

		for i in range(L//C):
				q_i, k_i, w_i = Q[i], K[i], W[i]
				u_i = U[i] - w_i @ S # 关键代码 the corrections, all of one chunk
				o_inter = q_i @ S
				A_i = (q_i @ k_i.t()).tril() #qk.t
				o_intra = A_i @ u_i # attention @ v (with corrections, so u)
				S += k_i.t() @ u_i # update state with addition
				O[i] = o_intra + o_inter #update output with flash + recurrent
		return O.reshape(L, d)
上面代码做到的是:假设序列长度为 $L$,chunk 大小为 $C$,那么原来需要做 $L$ 次逐 token 的状态更新;现在只需要做 $L/C$ 次逐 chunk 状态更新。
为了理解代码动机,先来看一个例子:
假设 $C=3$, 并且这个 chunk 开始之前的状态为 $S_0$。
第一个 token,$u_1 = \beta_1(v_1 - k_1 S_0)$,更新后,$S_1 = S_0 + k_1^\top u_1$;
第二个 token,$u_2 = \beta_2(v_2 - k_2 S_1)$,把 $S_1$ 展开,$u_2 = \beta_2(v_2 - k_2 S_0) - \beta_2(k_2 k_1^\top) u_1$
第三个 token,$u_3 = \beta_3(v_3 - k_3 S_2)$,而 $S_2 = S_0 + k_1^\top u_1 + k_2^\top u_2$
所以,$u_3 = \beta_3(v_3 - k_3 S_0) - \beta_3(k_3 k_1^\top) u_1 - \beta_3(k_3 k_2^\top) u_2$ 。
可以看到,chunk 内的依赖都是下三角的
$$u_1 = b_1$$
$$u_2 = b_2 - a_{21} u_1$$
$$u_3 = b_3 - a_{31} u_1 - a_{32} u_2$$
其中 $b_t = \beta_t(v_t - k_t S_0)$ ,$a_{tj} = \beta_t k_t k_j^\top$。
根据这个规律,我们可以将整个 chunk 的 $u_t$ 堆叠起来:
$$D = \begin{bmatrix} u_1 \ u_2 \ \vdots \ u_C \end{bmatrix} \in \mathbb{R}^{C \times d}$$
定义严格下三角矩阵:
$$A_{tj} = \begin{cases} \beta_t k_t k_j^\top, & j < t \ 0, & j \ge t \end{cases}$$
那么前面的递推可以统一写成,$D = B - AD$,也就是 $(I + A)D = B$。所以 $D = (I + A)^{-1}B$。
而 $B = V_\beta - K_\beta S_0$。其中 $V_\beta = \text{diag}(\beta)V$, $K_\beta = \text{diag}(\beta)K$$
因此 $D = (I + A)^{-1}(V_\beta - K_\beta S_0)$
定义 $T = (I + A)^{-1}$, 则 $D = T V_\beta - T K_\beta S_0$
继续定义 $U = T V_\beta, \quad W = T K_\beta$
最终得到 $\boxed{D = U - W S_0}$,也就是代码中的u_i = U[i] - w_i @ S。
这里的 $u_i$ 不是一个 token 的 $u$,而是:
$$W_i S \in \mathbb{R}^{C \times d}$$
包含当前 chunk 的全部 C 个 delta update,一次矩阵乘法同时得到 C 行:
第 1 行:u₁ 所需的状态修正
第 2 行:u₂ 所需的状态修正
...
第 C 行:u_c 所需的状态修正
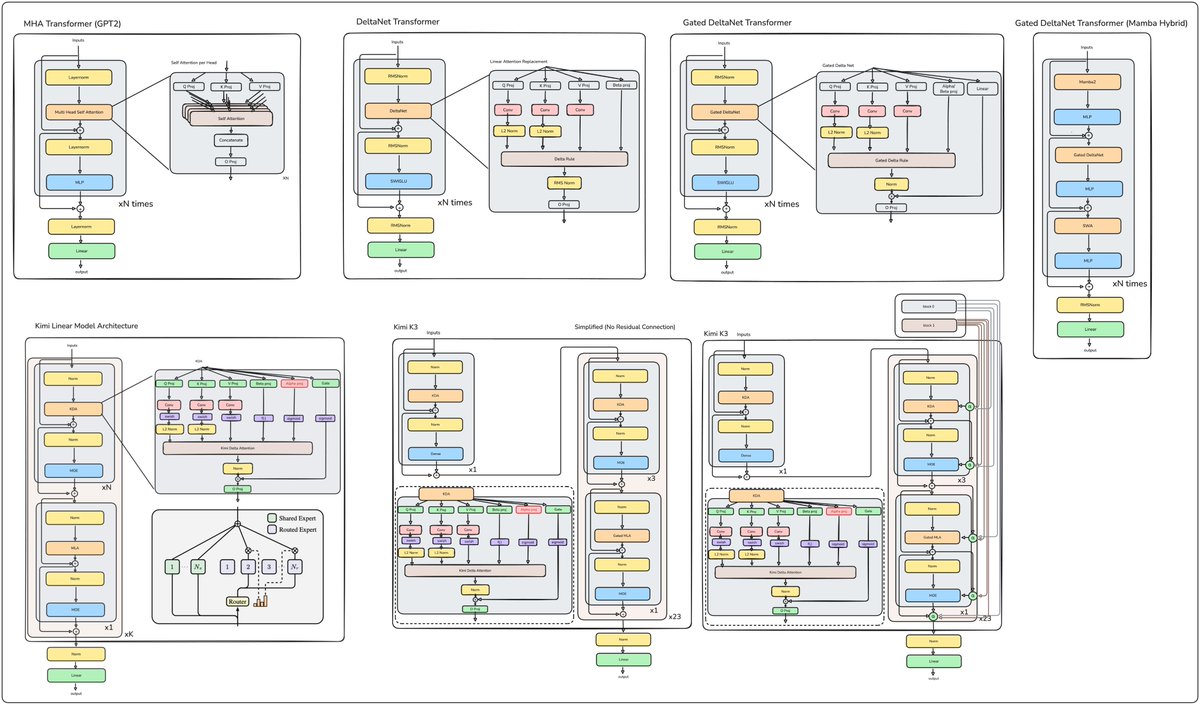
This gets us to our first comparison point: MHA vs DeltaNet Transformers:
![[from-gpt2-to-kimi3-13.jpg]]
最后让我们好好对比下,传统Attention经历了 Linear Attention 再到DeltaNet,整体架构发生了什么变化:
| GPT-2 MHA | DeltaNet | |
|---|---|---|
| token mixing | softmax self-attention | recurrent delta-rule state |
| 投影 | $Q, K, V$ | $Q, K, V, \beta$ |
| 历史表示 | 每个历史 token 的 KV | 固定大小状态 $S$ |
| 状态更新 | 无显式 recurrent state | 读取旧值后进行 delta 修正 |
| 局部建模 | attention 自然完成 | Q/K/V 前加入短卷积 |
| Q/K 处理 | 缩放点积 | L2 normalization |
| norm | LayerNorm | RMSNorm |
| FFN | 普通 MLP | SwiGLU |
| prefill 复杂度 | 通常随 $N^2$ 增长 | chunkwise 实现可近似随 $N$ 线性增长 |
| decoding cache | KV cache 随 $N$ 增长 | 固定大小状态 |
左边是典型的 pre-norm Transformer:
$$X \rightarrow X + \text{Attention}(\text{Norm}(X)) \rightarrow X + \text{MLP}(\text{Norm}(X))$$
右边做了三组主要修改:
- LayerNorm 改成 RMSNorm;
- Multi-Head Self-Attention 改成 DeltaNet;
- 普通 MLP 改成 SwiGLU。
$$X \rightarrow X + \text{DeltaNet}(\text{RMSNorm}(X)) \rightarrow X + \text{SwiGLU}(\text{RMSNorm}(X))$$
细节1 :
图中 $Q, K, V$ 在进入 Delta Rule 前先经过了 Conv。
这里通常表示沿序列方向进行短程的一维卷积:$\widetilde{Q}t = \text{Conv}(Q{t-r:t})$,类似地得到 $\widetilde{K}_t, \widetilde{V}_t$。
卷积的作用是先提供局部上下文混合。例如当前 token 的 key 不只依赖自身,还可以吸收附近几个token 的信息。
可以把它理解为:
- Conv:负责很短距离的局部模式;
- Delta state:负责长距离、固定状态的信息记忆。
标准 attention 本身可以直接访问附近 token,而 recurrent linear attention 的局部建模能力有时较弱,因此加入短卷积通常很有帮助。
细节2 :
图中 Conv 后,$Q$ 和 $K$ 还经过 L2 Norm,这样 $q_tk_j\top$ 更接近 cosine similarity,数值范围也更稳定。
尤其对 DeltaNet 来说,状态转移中有 $I−β_tk_t\top$
如果 $k_t$ 的模长没有控制,更新尺度可能不稳定。单位化 $k_t$后 $∥k_t∥^2=1$, 使擦除和写入的尺度更可控。
图中没有给$V$ 做 L2 normalization,因为 $V$ 表示要写入的实际内容,其幅值本身可能携带信息。
细节3 :
RMSNorm 与 LayerNorm 的区别
GPT-2 一侧使用 LayerNorm:
$$\text{LN}(x) = \frac{x - \mu}{\sqrt{\sigma^2 + \epsilon}} \gamma + \beta$$
DeltaNet 一侧使用 RMSNorm:
$$\text{RMSNorm}(x) = \frac{x}{\sqrt{\frac{1}{d} \sum_j x_j^2 + \epsilon}} \gamma$$
RMSNorm 不减均值,只按均方根缩放,计算更简单(计算每个元素的平方并求和,这个过程完全独立,只需要对数据进行一次遍历;而计算均值和方差需要两次遍历)。这和DeltaNet本身没有关系,只是一组更加现代化的架构选择。
细节4:
MLP 与 SwiGLU 的区别
GPT-2 一侧使用普通 MLP,常见形式是:
$$\text{MLP}(x) = W_2 \phi(W_1 x)$$
DeltaNet 一侧采用 SwiGLU:
$$\text{SwiGLU}(x) = W_o [\text{SiLU}(W_a x) \odot (W_b x)]$$
它有两条输入投影分支:
- 一条经过 SiLU,作为 gate;
- 另一条保存内容;
- 两者逐元素相乘。
SwiGLU 与 Delta Rule 没有必然的数学关系,它只是现代语言模型中常见、通常比早期 GPT-2 MLP 更有效的 FFN 设计。
为什么 SwiGLU 通常比普通 MLP 更有效呢?
-
门控机制(Gating Mechanism):普通 MLP 只是对变换后的特征进行统一的非线性激活 $\phi$。而 SwiGLU 引入了一根“门控通道” $\text{SiLU}(W_a x)$,可以动态控制另一条通道 $(W_b x)$ 中哪些信息应该通过。这种多线性(Bilinear)控制赋予了模型更强的表达能力。
-
SiLU 的平滑双稳态特性:SiLU(Swish)激活函数公式为 $\text{SiLU}(x) = x \cdot \text{sigmoid}(x)$。相比于传统 MLP使用的 GeLU 或 ReLU($\text{ReLU}(x) = \max(0, x)$),SiLU 在负值区域有微弱的梯度流入,且整体更加平滑,这有助于深度网络在大规模参数训练时的梯度流动和稳定收敛。
来进行一个High Level的总结吧:
传统Attention模型如GPT2的长期记忆方式是:
保留所有历史 token 的 K 和 V,再由 Q 逐一匹配
DeltaNet模型的长期记忆方式是:
把历史写入固定状态 $S$(所有历史token的信息都被压缩在里面),再由 $Q$ 读取。
Gated Delta Net
We now have a method for making precise changes to the cache. With each new fact (each new key vector), we can look at exactly the old information stored at that point and replace it with the new information we want to attend to.
其实我们目前看到的DeltaNet进行的是单点精确修改。
$$S_t = S_{t-1} + \beta k_t^T (v_t - k_t S_{t-1})$$
其中:
$$v_t - k_t S_{t-1}$$
表示:
当前 key $k_t$ 在旧缓存里对应的信息,和我希望它变成的信息之间的差异。
例如缓存里有:
Alice -> works at Google
Bob   -> lives in London
Carol -> likes coffee
现在模型看到新信息:
Alice -> works at OpenAI
那么输入 $k_t = Alice$, $v_t = works\ at\ OpenAI$
Delta Rule 可以计算:
旧:
Alice -> Google
新:
Alice -> OpenAI

difference:
Google -> OpenAI
然后修改 Alice 对应的部分。
也就是说,它需要 一个明确的 key $k_t$ 和一个新的目标值$v_t$,它才能知道哪个记忆应该改成什么。
However, this mechanism can forget only an association for which it has a specific replacement. It cannot efficiently clear multiple associations during a context switch or decay memory generally to free capacity.
但是有个问题,如果之前的信息都不那么重要了,我们希望模型忘记掉之前的那批信息,当前这种机制就无法实现。其实忘掉之前的信息很简单,之前的信息都被压缩在状态$S_{old}$,只要模型存在类似$S_{old} \ → \ 0.1S_{old}$ 的机制,就可以做到这一点。
If we were doing purely additive linear attention:
Adding the ability to forget would be simple. We'd just need a parameter controlling the forgetful state:
如果是在做普通的Linear Attention,那么就是加个参数 alpha 的事情,很简单。
S_old=cache
S_new=k@v
# cache=S_old+S_new
cache=alpha * S_old + S_new
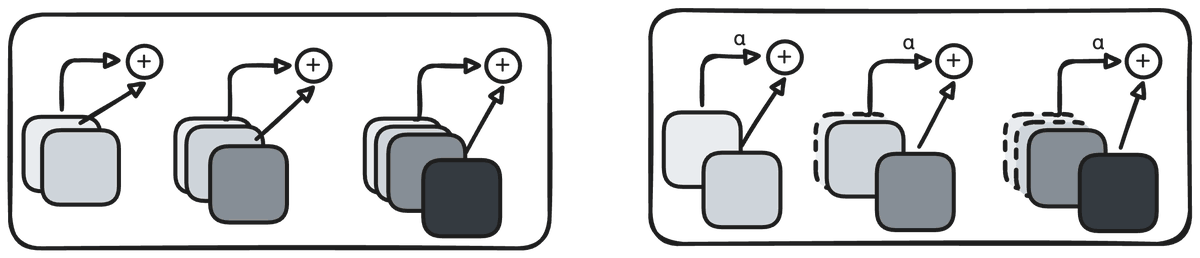
This is the Mamba-2 contribution. We decay the previous cache, then add the new cache at full strength, preventing the state from growing without bound.
Uniformly decaying all key-value associations at each time step by a dynamic ratio is a working approach, and it's what Mamba does. But it doesn't account for the varying importance of different key-value associations.
That is, if the model needs to forget one specific association, all associations are forgotten equally. The Delta rule, in contrast, can update a single fact but has no way to make the rest of the facts decay.
这是Mamba 式的 gated update,不过这种衰减是全局的,状态中所有 key-value 关联都会受到同样 alpha 程度的衰减。模型不能只忘掉其中一个事实而保留其他事实。
So the Gated Delta rule combines Mamba's gated update rule with the Delta rule. It adds a parameter, alpha, that switches to the pure Delta rule when set to one and clears the memory when set to zero. The challenge is implementing this with the same parallel-chunks method.
Gated Delta Rule 结合了两种操作:
- 用 $\alpha_t$ 对整个旧状态进行衰减;
- 用 Delta Rule 精确修正当前 key 对应的关联。
按照下面图片中代码对应的约定,可以写成 $\bar{S}{t-1} = \alpha_t S{t-1}$,
先衰减旧状态,然后计算当前 key 在衰减后状态中的旧值 $\hat{v}t = k_t \bar{S}{t-1} = \alpha_t k_t S_{t-1}$。
计算需要写入的误差 $u_t = \beta_t (v_t - \alpha_t k_t S_{t-1})$,
最后写入 $S_t = \alpha_t S_{t-1} + k_t^\top u_t$。
合并起来是 ${S_t = \alpha_t S_{t-1} + \beta_t k_t^\top (v_t - \alpha_t k_t S_{t-1})}$。
这里两个 gate 的职责不同。
$\alpha_t$控制整体遗忘,它回答“之前的整个缓存还应该保留多少?”;
$\beta_t$则 控制当前关联的修改强度,它回答当前这个 $k_t \rightarrow v_t$ 关联应该写入多强?
当 $\alpha_t = 1$,$S_t = S_{t-1} + \beta_t k_t^\top (v_t - k_t S_{t-1})$,这就是普通 Delta Rule。
alpha set to one switches to the pure Delta rule.
当 $\alpha_t \rightarrow 0$,旧状态贡献消失,$\alpha_t S_{t-1} \rightarrow 0$
误差变成 $u_t \rightarrow \beta_t v_t$,状态变成 $S_t \rightarrow \beta_t k_t^\top v_t$
严格地说,$\alpha_t = 0$ 清除的是之前的旧记忆,当前 token 的新关联仍然会被写入。因此它不是更新后状态完全为零,而丢弃过去,然后从当前 token 重新开始建立状态。
在实际实现中,$\alpha_t$ 通常会被限制为严格大于零,因为后面需要计算累计乘积的比值。
逐 token 串行执行很简单:
S = alpha[t] * S
u = beta[t] * (v[t] - k[t] @ S)
S = S + k[t].T @ u
但 DeltaNet 希望在一个 chunk 内尽可能并行。问题在于,每一个时刻的旧状态都会经历不同次数的衰减。以下的设计说明了如何实现并行。
首先假设一个 chunk 有 $C$ 个 token,定义 $\gamma_r = \prod_{j=1}^r \alpha_j$,
代码中对应:
g = alpha.cumprod(-1)
因此:
g[r] = alpha[1] * alpha[2] * ... * alpha[r]
它表示:
chunk 开始时的状态 $S_0$,到第 $r$ 个 token 时累计保留了多少。
所以 chunk 初始状态到第 $r$ 个位置时变成 $\gamma_r S_0$
The implementation uses the same DeltaNet reparameterization described in the previous section. The mathematics is nearly identical, with one addition: a data-dependent scalar between zero and one that controls the decay of the previous state. This combines effective key-value association learning with adaptive memory management.
The corresponding code changes are shown below:
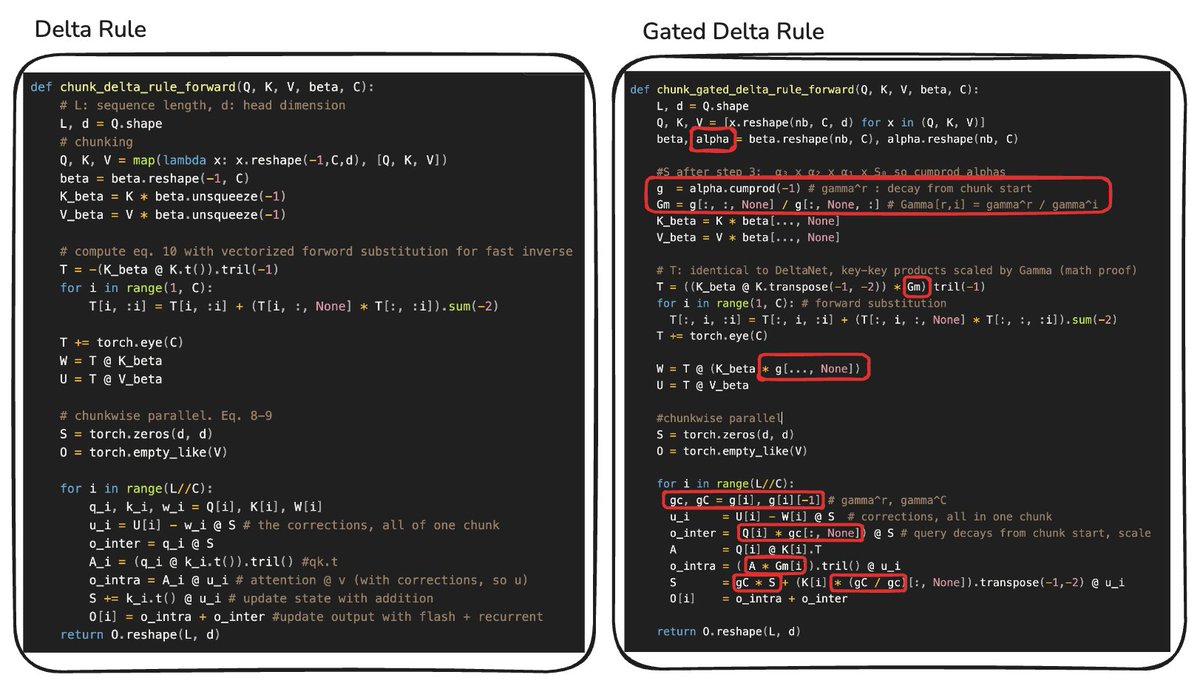
The γʳ/γⁱ term accounts for cumulative decay. A token written at time step x and read at x+t has been multiplied by αₓαₓ₊₁αₓ₊₂…αₓ₊ₜ. This is the multiplicative analogue of a prefix-sum calculation.
假设某条信息是在 chunk 内第 $i$ 个 token 写入的,现在在第 $r$ 个 token 读取,且 $r \ge i$。
这条信息只会经历 $i$ 之后的衰减 $\alpha_{i+1}\alpha_{i+2}\cdots\alpha_r$,
利用累计乘积,可以写成 $\frac{\gamma_r}{\gamma_i} = \frac{\alpha_1\alpha_2\cdots\alpha_r}{\alpha_1\alpha_2\cdots\alpha_i} = \alpha_{i+1}\cdots\alpha_r$,
所以 $\boxed{\frac{\gamma_r}{\gamma_i}}$ 表示在位置 $i$ 写入的信息,传播到位置 $r$ 时还剩多少。
代码中:
Gm = g[..., :, None] / g[..., None, :]
就是得到一个 $C \times C$ 矩阵 $Gm_{r,i} = \frac{\gamma_r}{\gamma_i}$ 。
举例说明这个矩阵具体是怎么样的:
假设 chunk 中 $\alpha = [0.8, 0.5, 0.9]$,
累计乘积如下:
$$\gamma_1 = 0.8$$
$$\gamma_2 = 0.8 \times 0.5 = 0.4$$
$$\gamma_3 = 0.8 \times 0.5 \times 0.9 = 0.36$$
因此:
$$g = [0.8, 0.4, 0.36]$$
到第 3 个位置时只剩 $\gamma_3 S_0 = 0.36 S_0$。
第 1 个 token 写入的信息传播到第 3 个位置时的比例是$\frac{\gamma_3}{\gamma_1} = \frac{0.36}{0.8} = 0.45$,也就是 $0.5 \times 0.9 = 0.45$。
第 2 个 token 写入的信息传播到第 3 个位置时的比例是$\frac{\gamma_3}{\gamma_2} = \frac{0.36}{0.4} = 0.9$,对应只经历第 3 步的衰减。
第 3 个 token 写入的信息由于在第 3 步立即读取:$\frac{\gamma_3}{\gamma_3} = 1$,因此下三角部分的累计衰减矩阵是:
$$\begin{bmatrix} 1 & 0 & 0 \ 0.5 & 1 & 0 \ 0.45 & 0.9 & 1 \end{bmatrix}$$
这就是代码中 Gm 在因果下三角区域的含义。
设一个 chunk 开始时的状态为 $S_0$,第 $r$ 个位置的状态可以展开成:
$$\boxed{S_r = \gamma_r S_0 + \sum_{i=1}^r \frac{\gamma_r}{\gamma_i} k_i^\top u_i}$$
其中:
- $\gamma_r S_0$:chunk 之前的旧状态,经过前 $r$ 个 gate 后的结果;
- $k_i^\top u_i$:第 $i$ 个 token 写入的 correction;
- $\gamma_r / \gamma_i$:该 correction 从位置 $i$ 传播到位置 $r$ 时后的衰减。
输出为:
$$o_r = q_r S_r$$
所以:
$$\boxed{o_r = \gamma_r q_r S_0 + \sum_{i=1}^r \frac{\gamma_r}{\gamma_i} (q_r k_i^\top) u_i}$$
这正好被代码拆成两部分 o_inter(来自 chunk 之前的状态) , o_intra 来自当前 chunk 内部的写入。
接下来对上图右侧Gated Delta Rule代码的关键部分进行更加详细的解释,以便于理解这时候是如何实现并行的:
g = alpha.cumprod(-1) # 计算累计gate, 表示 chunk 初始状态传播到位置 r 时的累计衰减
Gm = g[..., :, None] / g[..., None, :] # 构造任意两个位置之间的衰减,得到一个下三角矩阵,每个元素表示位置 i 写入的信息到位置 r 时的剩余比例。
T = -((K_beta @ K.transpose(-1, -2)) * Gm).tril(-1) # 修改 token 之间 correction 的依赖
W = T @ (K_beta * g[..., None])
# 第 r 个位置读取 chunk 初始状态时,看到的不是 S_0,而是 γ_r*S_0
# 因此 correction 中对应初始状态的部分是:
# −β_r * γ_r * k_r * S_0
# 所以必须把 β_r * k_r 变成 β_r * γ_r * kr,也就是:
K_beta * g[..., None]
# 随后
u_i = U[i] - W[i] @ S # 计算整个 chunk 的 correction。
U = T @ V_beta
o_inter = (Q[i] * gc[..., None]) @ S # 其中gc = g[i]
# 即 chunk 内所有位置的:[γ1,γ2,…,γC]
# 第 r 个 query 读取 chunk 初始状态时应该得到:qr(γrS0)=(γrqr)S0
#所以代码把每个 query 乘以对应的 γr
#普通 DeltaNet 中没有整体衰减,因此原来只是:
o_inter = q_i @ S
# chunk 内部的注意力贡献
# 首先计算普通 query-key 相似度:
A = Q[i] @ K[i].T
o_intra = (A * Gm[i]).tril() @ u_i # 位置 i 的写入传播到位置 r 时已经衰减为 γr / γi
# 更新 chunk 结束时的状态
S = gC * S + (
K[i] * (gC / gc)[..., None]
).transpose(-1, -2) @ u_i # #
# chunk 结束时,初始状态经过整个 chunk 的衰减: gC * S
# gC / gc
#就是:
#[γC/γ1, γC/γ2, …, γC/γC]
🎉 如果你学到了这里,那么你对一整条linear attention的发展、优化历史就了解得差不多了,给你来个小小总结表格作为彩蛋:
| 方法 | 状态更新 | 能力 |
|---|---|---|
| 加法线性注意力 | $S_t = S_{t-1} + k_t^\top v_t$ | 只会累积 |
| Gated additive / Mamba 式 | $S_t = \alpha_t S_{t-1} + k_t^\top v_t$ | 能整体遗忘,但不能精确替换某条关联 |
| Delta Rule | $S_t = S_{t-1} + \beta_t k_t^\top (v_t - k_t S_{t-1})$ | 能精确修改关联,但不擅长整体遗忘 |
| Gated Delta Rule | $S_t = \alpha_t S_{t-1} + \beta_t k_t^\top (v_t - \alpha_t k_t S_{t-1})$ | 同时支持整体衰减与定点修改 |
KDA/Kimi Linear
At this point, researchers began experimenting with hybrid models that combine multiple forms of attention within one architecture, like Gated DeltaNet with Mamba.
有了 Gated DeltaNet 之后,Attention机制里面的记忆、遗忘和加速的问题基本被解决,人们逐渐开始探索混合不同机制的模型结构。
Kimi Linear drew attention for one central claim: under controlled comparisons, it outperformed full attention. The authors presented it as a drop-in architectural replacement with better quality and up to 6x higher decode throughput.
Kimi Linear improves on Gated DeltaNet by introducing fine-grained gating. Instead of a single scalar decay, it learns a separate decay value for each channel.
Kimi Linear则是通过更细粒度的遗忘设计,进一步提升了Gated DeltaNet的表现。用一句话总结:
Gated DeltaNet 学习“每个 token 应该遗忘多少”;Kimi Linear 进一步学习“每个 channel(维度)应该遗忘多少”。
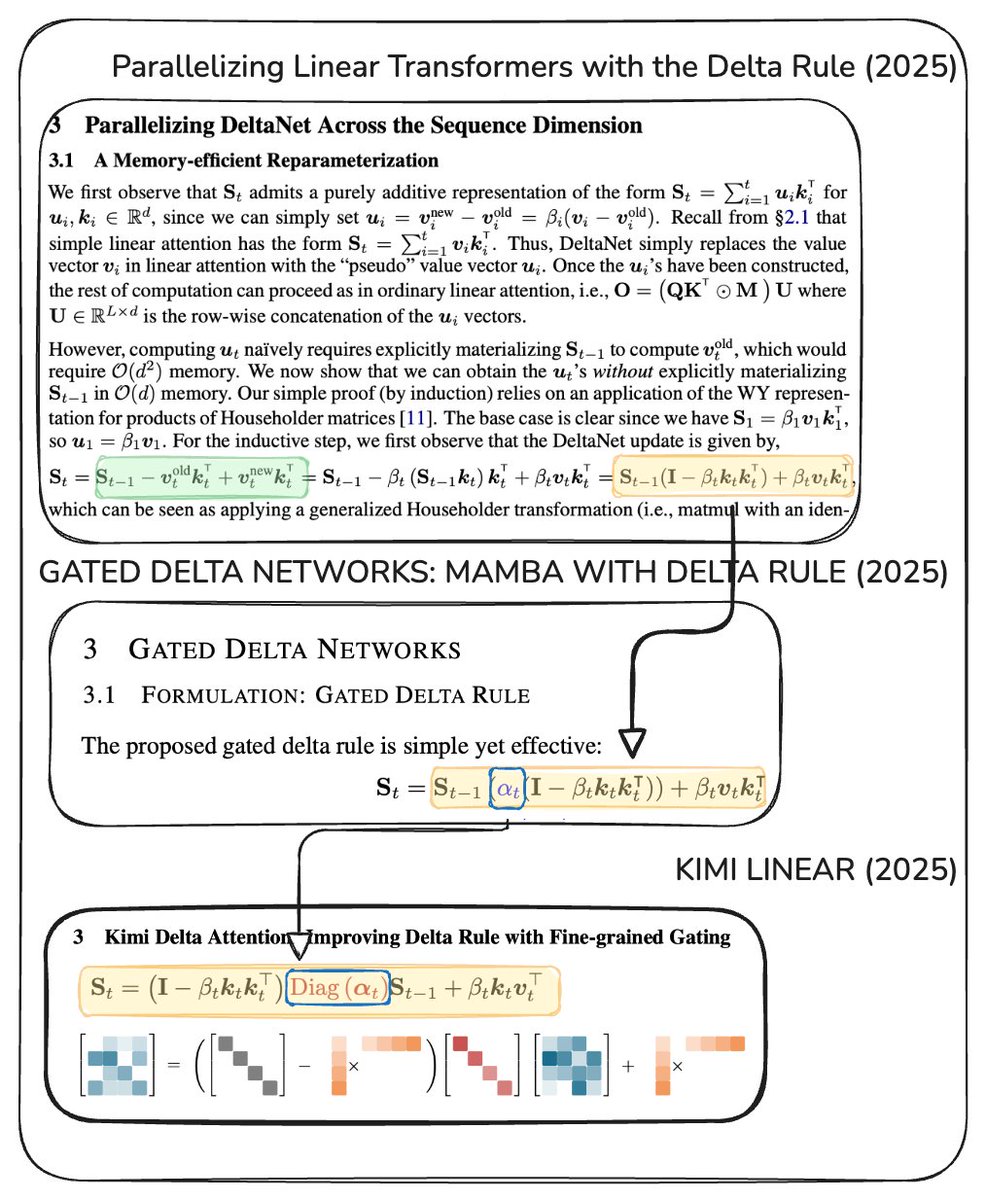
The KDA update rule remains similar, but the code now looks more like this:
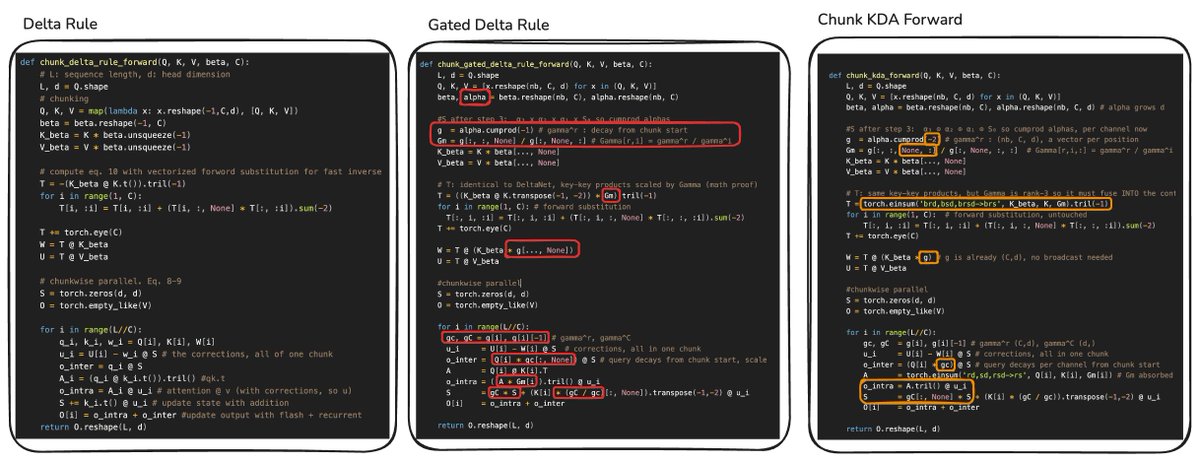
| 模块 | Gated Delta Rule | Chunk KDA Forward (Kimi Linear) |
|---|---|---|
| 核心思想 | Delta Rule + token级遗忘 | Delta Rule + channel级遗忘 |
| decay 参数 | alpha | alpha |
| decay shape | (batch, chunk) | (batch, chunk, dim) |
| decay 粒度 | 每个 token 一个 decay | 每个 token 每个 channel 一个 decay |
| 输入 reshape | Q, K, V -> (nb, C, d) | Q, K, V -> (nb, C, d) |
| beta处理 | beta.reshape(nb, C) | beta.reshape(nb, C, d) |
| alpha处理 | alpha.reshape(nb, C) | alpha.reshape(nb, C, d) |
| key/value修正 | 同左 | 同左,但 beta 现在可以按 channel 控制 |
| 累计衰减 $\gamma$ | g = alpha.cumprod(-1) | g = alpha.cumprod(-2) |
| $\gamma$ 含义 | $\gamma_t = \prod_i \alpha_i$ | $\gamma_{t,d} = \prod_i \alpha_{i,d}$ |
| 为什么 cumprod 维度不同 | alpha 只有时间维 | alpha 有时间+channel维,需要沿时间累计 |
| 衰减矩阵 $G$ | Gm = g[..., :, None] / g[..., None, :] | Gm = g[:, :, None, :] / g[:, None, :, :](概念上) |
| $Gm$ 含义 | token $i \rightarrow$ token $r$ 的累计衰减 | channel-wise token $i \rightarrow$ token $r$ 的累计衰减 |
| token间影响矩阵 $T$ | T = -(K_beta @ K.T * Gm).tril(-1) | T = torch.einsum(..., K_beta, K, Gm).tril(-1) |
| $T$ 变化原因 | 加入时间衰减 | 加入时间+channel衰减 |
| forward substitution | 保持 | 保持 |
| correction计算 | U = T @ V_beta | U = T @ V_beta |
| 初始state影响 | Q[i] * gc | Q[i] * gc(gc 是 vector) |
| chunk state更新 | S = gc * S + (K * (gc / gc_i)).T @ u | 同左,但 gc / gc_i 是 vector |
| state decay | scalar decay | 每个 channel 独立 decay |
| Here, alpha.reshape(nb, C, d) captures the paper’s most significant contribution: fine-grained control over memory decay. | ||
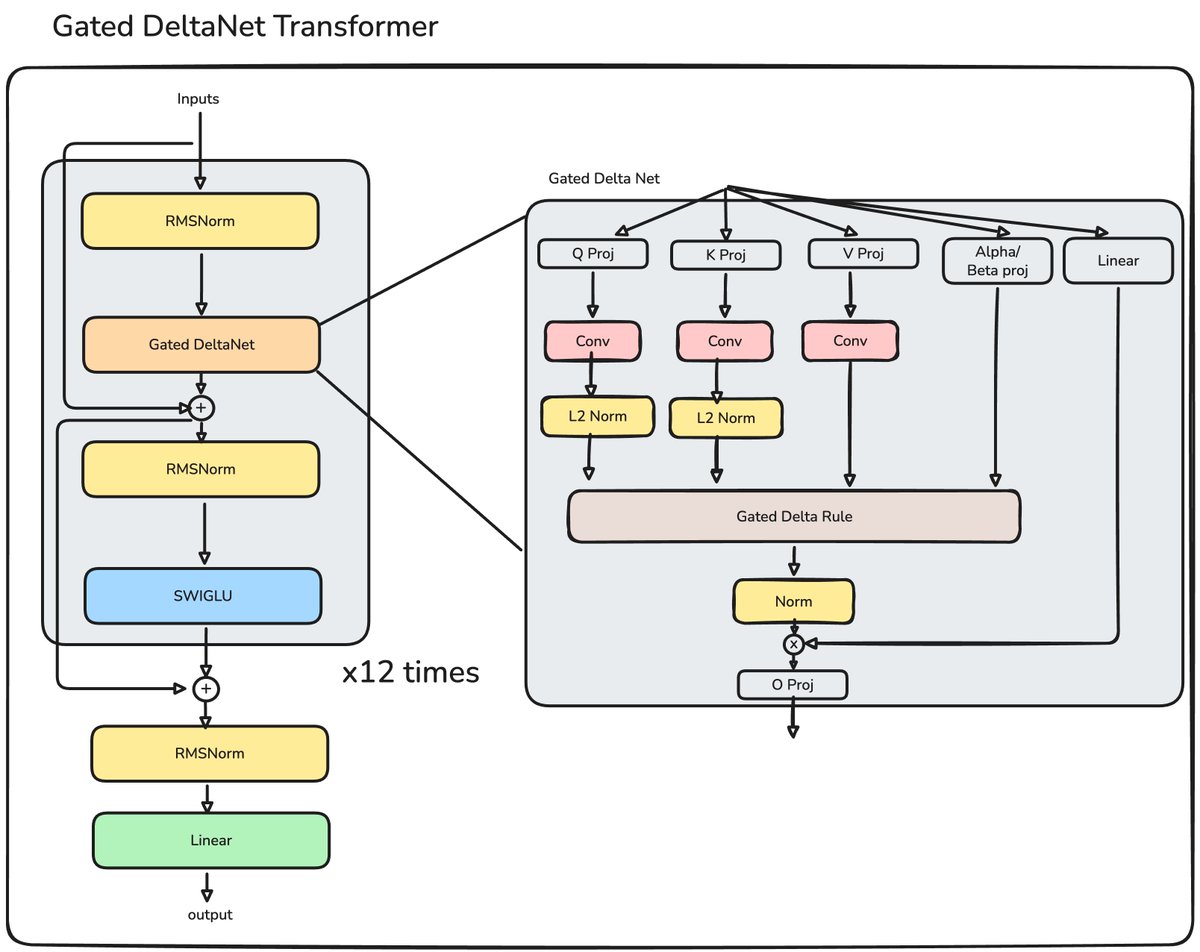
| Placed beside the DeltaNet Transformer, the Kimi Linear architecture introduces three major changes: |
- It uses a hybrid system that interleaves Multi-head Latent Attention (MLA) layers.
- It replaces the MLP with a Mixture-of-Experts (MoE) layer.
- It adds capacity to DeltaNet through the alpha projection.
除了KDA,Kimi Linear还有这几个模型架构上的新设计:
- 从下方右图可以看到,第一个块使用了KDA,但是第二个块使用了MLA,所以说是采用了一个hybrid system。这样做的目的是使用MLA来弥补linear attention 的表达能力不足。
- 之前我们提到SwiGLU是比传统MLP更加现代化的FFN设计,但是这里,它被换成了MOE,通过更多的参数量,换取更高效准确的决策。
- 下方右图有个红框,表示Kimi Linear加入了Alpha Projection。这里面的Alpha就是用来表示“每个 channel(维度)应该遗忘多少”。
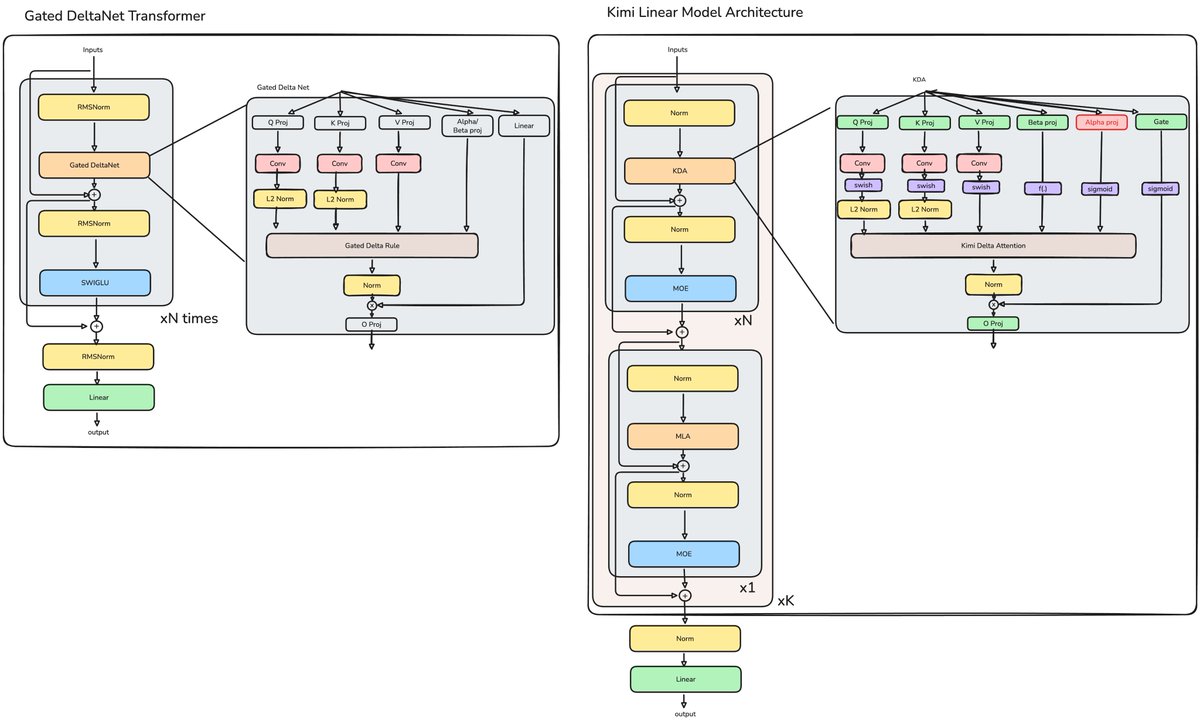
The later sections cover MLA and MoE in more detail. For now, the important point is that this is not blind scaling. The additional capacity has a specific mathematical purpose: the per-channel scale gives the model finer control over memory decay.
Scaling laws remain relevant, but capacity must be added in the right place and in a form the system can use. Each architecture in this progression adds capacity to address a concrete limitation in the preceding system.
关于MLA和MOE,之后的章节会有更详细的介绍。到目前,我们可以看到,并不是参数更多,模型越堆越大,效果更好,只有伴随着模型结构和算法的进步,我们才实现越来越可靠的scaling。
Kimi K3
Ultimately, the KimiK3 language backbone looks similar to the Kimi Linear model above. It contains 23 four-layer macrocycles. In each macrocycle, three layers use Kimi Delta Attention and the fourth uses Multi-head Latent Attention. The first layer uses a dense feed-forward network; every remaining layer uses a latent Mixture-of-Experts.
让我们来看看最新出的KimiK3吧!Kimi K3 基本沿用了上面一节提到的Kimi Linear的思想,但是进一步扩大规模,并加入一些针对超大模型训练/推理的问题的优化。
首先和Kimi Linear一样,Kimi K3 采用混合Attention 架构:
一共
23×4=92
个 attention block。
每 4 层:
Layer 1: KDA
Layer 2: KDA
Layer 3: KDA
Layer 4: MLA
重复 23 次。
At first glance, the changes from Kimi Linear appear modest:
乍一看,从Kimi Linear到Kimi K3变化没有很大:
A substantial increase in scale
Blockwise AttnRes every 12 layers
MLA query LoRA and output gating
Latent-space MoE
SiTU activations
Gated MLA
| 技术/架构变动 | 核心目的 |
|---|---|
| Blockwise AttnRes | 解决深层 residual 问题 |
| MLA query LoRA | 降低 MLA KV/query 成本 |
| Output gating(Gated MLA) | 控制信息流 |
| Latent MoE | 增加容量 |
| SiTU activation | 优化 FFN |
KDA supplies constant-state recurrent memory, while periodic MLA layers retain full softmax retrieval over the context. The following simplified visualization provides a useful reference for the changes discussed below.
为什么Kimi K3要混合使用KDA和MLA呢,因为KDA维护了一个$S_t$ ,是一个不断更新的状态,包含过去和新的信息,但是这是一个粗粒度的信息;而MLA则保留了更细粒度的信息。
什么是MLA呢?
MLA(Multi-head Latent Attention,多头潜在注意力)是 DeepSeek 在 DeepSeek-V2 中提出的一种 Attention 结构。它主要解决 Transformer 在长上下文推理时 KV Cache 太大的问题。
普通Attention机制的KV cache非常大,因为在推理的时候,比如要生成生成第10000个 token的时候,需要访问之前所有 token 的 $K_1,K_2,...,K_{9999}$(语言对过去信息的依赖)。因此保存$(K,V)$的KV Cache就很大。而MLA做的就是不直接缓存完整 K,V,而是缓存一个低维的“潜在表示”(compressed KV representation)。
这个潜在表示的启发思想很简单,首先,还记得Attention中Q,K,V是怎么来的吗?
对于第 $i$ 个token对应的向量表示$x_i$ ,让它通过三个线性层获得 $Q,K,V$ :
$$Q_i=x_iW_Q $$
$$K_i=x_iW_K $$
$$V_i=x_iW_V$$所以!K 和 V 本质上都是由 x 生成的。
那么,如果存在一个更小维度的表示 $c$ , 使得 $$K=cW_{UK}$$$$V=cW_{UV}$$
那么,比如原本 $x_i$ 是4096维度的,现在得到了一个512维度的$c$,我们就可以由$c$ 和 $W_{UK}$, $W_{UV}$得到K和V了,不用花原本那么多的空间存储KV Cache。也就是说,原本每个token需要存储一对4096维度的(K, V),现在只需要存储一个512维度的c了!存储位从8192 —> 512。
那么这个c要怎么得到呢?总之我们对c的要求有两个方面:
- 它是x的降维表示。
- 它可以恢复出原本的K和V。
由此,我们可以设计模型让它学会 怎么把重要的信息塞进一个压缩的表示c里面。
Encoder:  x→c
Decoder:  c→K,V
encoder是学习down projection压缩,而Decoder是恢复出原始的K和V信息,
整个过程是这样的:
                W_DKV
x(4096) ----------------> c(512)

                             W_UK
                         c ----------> K(4096)

                             W_UV
                         c ----------> V(4096)
这三个矩阵 $W_{DKV}$, $W_{UK}$, $W_{UV}$ 全部通过训练学习。
We will begin with the more direct changes: Gated MLA, latent-space MoE, and SiTU activations.
Gated MLA determines how much of each retrieved feature passes from MLA into the residual stream. It does this through element-wise multiplication with a gate projected from the input.
知道了MLA是什么之后,再来看看KimiK3里面用到的Gated MLA。这个Gate主要是用来控制残差连接里面的信息的。
普通 MLA 得到 attention 输出o之后,就直接加入 residual:x′=x+o
Kimi K3 则增加 gate g=σ(Wx),然后 x′=x+g⊙o
这个gate是在维度层面上工作的,目的是更细粒度地控制信息流,g 就是从输入 x 经过一个可学习的线性投影:
$$g_{raw}=xW_g$$
假设我们得到:
$$gt=[0.9,0.2,0.8,0.1]
$$
然后( o 是 MLA 得到的attention 输出):
$$o′=g_t⊙o_{MLA}$$
MLA output:

dimension:
1    2    3    4

0.3 -0.7 1.2 0.5


gate:

0.9 0.2 0.8 0.1


result:

0.27 -0.14 0.96 0.05
所以:
- 第1维保留90%
- 第2维压低到20%
- 第3维保留80%
- 第4维几乎关闭
讲完了MLA,那么MLA query LoRA又是什么呢?
这是对Q做的一个增强,因为Q(Query)决定了检索质量。
普通Q是:$Q=xW_Q$
此时我们觉得Q很重要,需要增强一下,但是我们不要重新学习一个巨大的矩阵 $W_{Q′}$ 。而是在原矩阵旁边加一个低秩更新:$W_{Q′}=W_Q+ΔW_Q$, 其中:$ΔW_Q=AB$
所以也就是原来的 query: $Q_{base}=xW_Q$ 再加一个小的修正 $Q_{LoRA}=xAB$
最终:$Q=Q_{base}+Q_{LoRA}$
说完K3的MLA Gate,现在来看它的MoE。
In a conventional MoE, a learned router uses dot-product similarity to send each token to a subset of expert networks. KimiK3 has 898 experts in total. Two are shared and process every token; of the remaining 896, the router selects 16 for each token.
K3的MOE架构总共有898 个 expert。其中 Shared experts 有2个,这是所有 token 都会经过的地方,是处理“公共知识”的专家。
而 Routed experts 有896个,但是router 最后会选择 其中的16个,例如对于token:
"quantum physics"
router只激活下面这些expert:
expert 31
expert 72
expert 204
...
16个
所以虽然模型参数巨大, 但是每个 token 只需要通过 2+16=18个 expert 的计算。
KimiK3 also changes the expert activation. Instead of applying SiLU to the up projection, multiplying it element-wise by the gate, and then applying the down projection, it uses SiTU:
d = x.shape[-1] // 2
gate = x[..., :d].to(torch.float32)
up = x[..., d:].to(torch.float32)
situ_a = self.beta * torch.tanh(gate / self.beta) * torch.sigmoid(gate)
if self.linear_beta is not None:
    up = self.linear_beta * torch.tanh(up / self.linear_beta)
return (situ_a * up).to(x.dtype)
在MoE里面,给每个token选定了expert后,下一步就是让token进入expert的模型内部计算了,一个 expert 本质上通常就是一个小 FFN,expert activation 指的是每个 expert 内部 FFN 用的非线性激活函数/门控激活,用于决定“这个 token 的哪些 feature 应该被非线性放大、压制或门控”。
K3也对expert activation 进行了改进,由SwiGLU转为SiTU。
先看普通 SwiGLU怎么做的:
$$FFN(x)=W_2(SiLU(W_1x)⊙W_3x)$$
步骤可以画成:
             x
          /     \
       W1         W3
       |          |
     gate         up
       |          |
     SiLU         |
       \          /
        element-wise ×
              |
             W2
              |
              y
Kimi K3 使用的 SiTU 代码如下:
situ_a = beta*tanh(gate/beta)*sigmoid(gate)
大概步骤就是:
              x
           /     \
         W3       W1
         |        |
       gate       up
         |        |
       SiTU      tanh限制
         \        /
          element-wise ×
                |
               W2
                |
              output
区别在于 SiLU 是 $xσ(x)$,SiTU是 $β tanh(x/β) σ(x)$;
直觉上来说,这样的好处是 $tanh$ 限制幅度。可以避免大模型训练:
- activation explosion;
- 数值不稳定。
但是就像下文提到的:
Without a fused kernel, new activation is almost 3x slower.
因为SiTU并不是硬件已有的优化算子。所以理论上好,实际上慢,需要 fused kernel来加速(把原本需要多个 GPU kernel 分别执行的操作,合并成一个 kernel 一次完成)。
The model also down-projects inputs to the shared experts and up-projects their final sum:
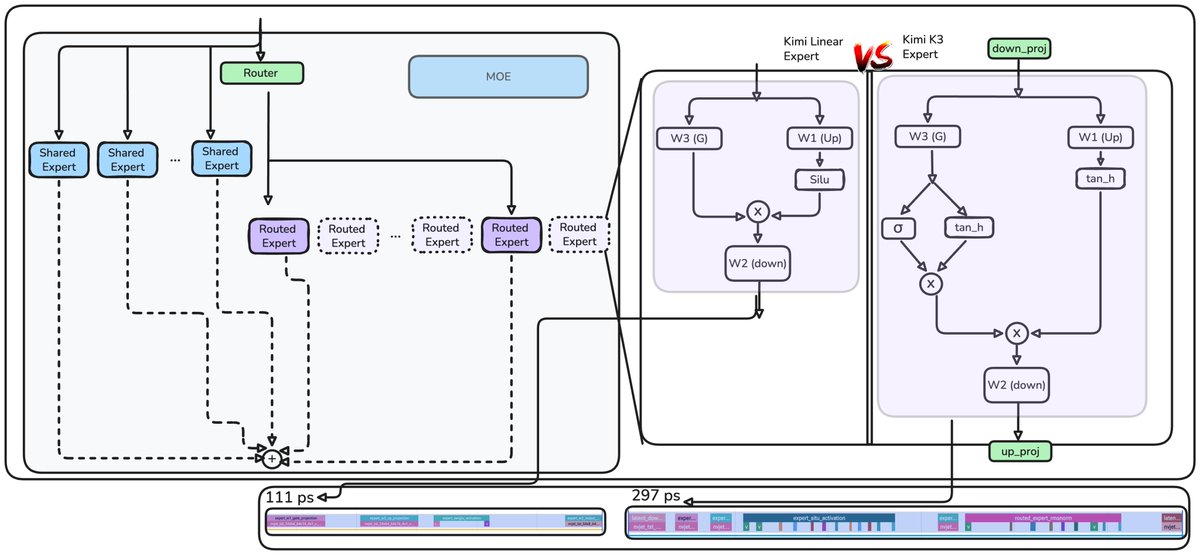
这张图解释的是 Kimi K3 对 MoE(Mixture-of-Experts)的一个重要优化:Latent-space MoE(潜空间 MoE)。
This illustrates a recurring challenge in model inference. Without a fused kernel, the new activation is almost 3x slower than the original path. One offsetting optimization is that the experts operate in a compressed latent space, which makes their forward pass much faster and nearly halves the FLOPs.
从上图右边我们可以看到K3除了expert activation有变化之外,还多了上下两个绿色模块down_proj 和 up_proj ,这就是latent space优化,具体来说,
Expert 内部矩阵非常大,例如输入:
$$x \in R^{4096}$$
expert里面进行如下的矩阵操作:
$$W_1 : 4096 \times 11008$$
计算量就有
$$4096 \times 11008$$
虽然每个 token 只激活 16 个 expert,但每个 expert 仍然很大,计算量就很大。
Kimi K3则是先做了一个降维,不要让 expert 看:$$x \in R^{4096}$$
而是先压缩:
$z=xW_{down}$
例如 4096→1024
然后expert 在这个压缩后的z上计算。
流程如下图所示:
原 hidden x
|
down_proj
|
↓
latent z
|
MoE experts
|
↓
latent output
|
up_proj
|
↓
hidden output
这个过程很熟悉对吧,前面提到的MLA也用了类似的过程来学会压缩x的原始表示,然后避免了大量KV Cache的产生。
The remaining changes are MLA query LoRA, output gating, and blockwise Attention Residuals every 12 layers. AttnRes adds roughly 2% inference latency, but provides two important benefits:
MLA query LoRA 和 output gating 上面都讲了,接下来会介绍 Attention Residuals。虽然它引入了2% 的推理延迟,但是看完下面一节,就可以理解它带来了两个好处:
Selective retrieval of earlier representations, which mitigates residual dilution and hidden-state growth A 1.25x compute advantage
AttnRes 不再把所有早期层等权相加,而是给每个早期表示一个动态权重,这样既避免所有历史信息一股脑累加,也能重新突出早期重要表示,因此缓解 dilution(某一层有用的信息被越来越多后续层的输出“稀释”掉) 和 hidden-state growth。
AttnRes and MLA address the same underlying limitation from different directions. KDA layers operate with constant-size state and must inevitably discard information. MLA retrieves from the token context, while AttnRes retrieves from earlier depth-wise representations.
MLA 和 AttnRes 表面上做不同的事,但背后都在解决“信息被压缩后会丢失”这个问题。
AttnRes
Thanks to @chloey3k for help with this section.
In each forward pass, the input passes through a stack of layers. Here, each layer consists of an attention block (KDA or MLA) and an MLP or MoE block. Normally, the input to each layer is the sum of the original embedding and every preceding layer's output, all weighted equally.
$$h_l = h_1 + \sum_{i=1}^{l-1} f_i(h_i)$$
Here, $h_i$ is the input to layer $i$, $h_1$ is the embedding of the current token (the last token in the sequence so far), and $f_i(h_i)$ is the output of layer i (an attention or MLP block).
回忆下基本的Transformer结构,都会有残差连接,以上的公式其实就是描述了残差连接的过程,也揭示了传统残差连接的缺陷: 所有历史层都被无差别相加。
首先解释下这个公式。假设有 $h1$ 作为最开始的 token embedding。
第一层做 $h_2=h_1+f_1(h_1)$ ; 第二层 $h_3=h_2+f_2(h_2)$。
展开就是 $h_3=h_1+f_1(h_1)+f_2(h_2)$
继续下去就是我们看到的公式 $h_l=h_1+\sum_{i=1}^{l-1} f_i(h_i)$
这里的 $f_i$ 可以理解成一个 Transformer sublayer,例如:
Attention
或者
MLP / MoE
所以 residual stream 本质上一直在做:
embedding
+ 第1层产生的信息
+ 第2层产生的信息
+ 第3层产生的信息
+ ...
The problem is the lack of selective access. Different layer types receive the same aggregated state, even though they may benefit from different weightings. Because the recurrence is purely additive, later layers must also learn increasingly large outputs to influence the accumulated residual, which can ==destabilize training==. Instead of treating all the layers equally, AttnRes multiplies each term of that sum by a specialized weight, which lets the model give more importance to whichever layers are most useful in context.
$$h_l = \alpha_0 \cdot h_1 + \sum_{i=1}^{l-1} \alpha_i \cdot f_i(h_i)$$
destabilize training就是破坏训练稳定性的意思。所有历史层信息无差别地相加起来,导致模型的负担越来越重。假设到了第50层,模型需要表达 “我现在特别需要第 7 层提取的实体信息”,还有 “第 20 层的 representation 对这个 token 没什么用”,那这种传统的残差连接是做不到的。
于是,AttnRes就给不同的层加上权重 $\alpha_i$ ,使得模型可以关注对当前上下文来说更有用的那些历史层。
Each weight $\alpha_i$ is computed from a query-key dot product. The query is learned for each layer, while the keys and values come from earlier residual-stream states. The scores are normalized to sum to one, then used to form a weighted combination of those states.
$\alpha_i$ 要如何计算呢?
假设推理当前来到第 $l$ 层,正在处理第 $t$ 个 token,历史第 $i$ 层对于这个 token 的 representation 是 $v_{i,t}$ 。先生成 key $k_{i,t} = \text{Norm}(v_{i,t})$
当前 layer $l$ 有一个 learned query $q_l$ (和普通attention的q不同,这是一个模型参数,会随着训练更新),然后计算layer level的注意力分数:$s_{i,t}^{(l)} = q_l^\top k_{i,t}$ (表示第 $l$ 层的 query,和 token $t$ 在第 $i$ 个历史 block 的 key 的匹配程度)
再沿着历史 layer $i$ 做 softmax:$\alpha_{i,t}^{(l)} = \text{softmax}i \left( s{i,t}^{(l)} \right) = \frac{\exp(q_l^T k_{i,t})}{\sum_{j=1}^N \exp(q_l^T k_{j,t})}$
最后计算分配给该token在第 $i$ 层信息的权重:$h_{l,t} = \sum_i \alpha_{i,t}^{(l)} v_{i,t}$ ,
举个具体例子:
假设现在是 Layer 50,有一个参数 $q_{50}$ 。
现在考虑两个 token:
token 100 = "Paris"
token 101 = "is"
假设之前保存了 4 个 depth block。
对于 "Paris" :
$$k_{1,100}, k_{2,100}, k_{3,100}, k_{4,100}$$
计算:
$$q_{50}^\top k_{1,100} = 0.2$$
$$q_{50}^\top k_{2,100} = 3.0$$
$$q_{50}^\top k_{3,100} = 0.5$$
$$q_{50}^\top k_{4,100} = 1.0$$
softmax 后可能:
$$\alpha_{\cdot,100} = [0.04, 0.78, 0.06, 0.12]$$
说明对于 "Paris"
Layer 50 最想重新读取 Block 2 时的表示。
但是对于 token "is" :
$$k_{1,101}, k_{2,101}, k_{3,101}, k_{4,101}$$
虽然 query 还是同一个:$q_{50}$,但可能得到 $\alpha_{\cdot,101} = [0.10, 0.05, 0.15, 0.70]$ 。
说明对于 "is"
Layer 50 更需要 Block 4 的表示。
所以:$q_l$ 是 layer-specific 的,而 $k_{i,t}$ 是 token-specific + depth-specific 的。因此最终的 αi,t(l) 依然是 token dependent。
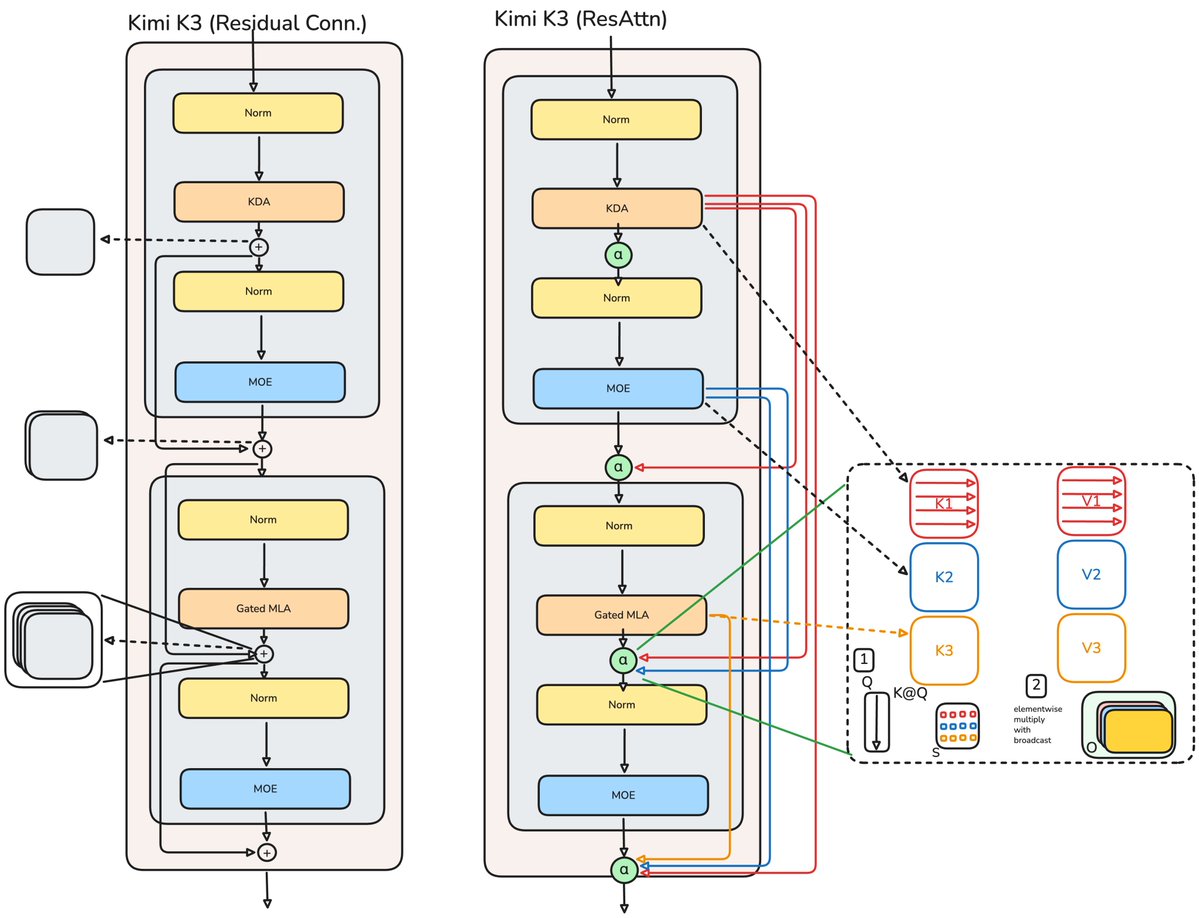
The model therefore does not have to condition only on its immediate predecessor. AttnRes gives each layer selective access to earlier layer outputs, allowing its learned query to retrieve the representations most useful for the current computation.
The pseudocode below applies the same idea at block granularity. A block is the element-wise sum of the attention and MLP outputs accumulated across 12 decoder layers, stored as a single depth representation for later AttnRes mixing.
例如 $B_1=ΔAttn_1+ΔMLP_1+⋯+ΔAttn_{12}+ΔMLP_{12}$ , 然后把 $B_1$ 作为一个整体保存。
Applying residual attention at every layer would add too much training and inference cost. Applying it only at fixed block boundaries captures most of the benefit at a lower cost. In KimiK3, each boundary occurs after 12 decoder layers. Across 23 four-layer macrocycles, this produces eight AttnRes blocks, which increases our inference speed.
对每层都做一次AttnRes太昂贵了,#于是提出 Block AttnRes 把很多 layer 合成一个 block。
Kimi K3 有 23×4=92 个 macrocycle layers,每 12 层形成一个 AttnRes block。因此大约 92/12≈7.67,也就是 8 个 block。
This is possibly the most important part of the block_attn_res function
V = torch.stack(blocks + [partial_block]) # [N+1, B, T, D]
K = norm(V)
logits = torch.einsum('d, n b t d -> n b t', proj.weight.squeeze(), K)
h = torch.einsum('n b t, n b t d -> b t d', logits.softmax(0), V)
return h
接下来解释一下上面的代码,
对于第一行,假设已经有:
Block 1
Block 2
Block 3
现在正在计算:
Block 4
那么 blocks 大概是:$[B_1,B_2,B_3]$ , 而 partial_block 就是当前 Block 4 目前为止已经累积的 residual。
V.shape = [N+1, B, T, D]
其中:
- N+1:历史 blocks + 当前 partial block
- B:batch size
- T:sequence length
- D:hidden dimension
比如:
8 blocks
batch = 16
sequence = 4096
hidden = 8192
那么大致:
[8, 16, 4096, 8192]
第一个维度就是 depth,这是整个代码的关键。
第二行:$V$既作为 Value,同时经过 RMSNorm 得到 $K$ , 作为 Key。
第三行,
logits = torch.einsum(      # enisum是一个通用张量运算函数
# 它的规则是,某个字母出现在输入中,但没有出现在 `->` 后面的输出中,就沿这个维度乘起来并求和
    'd, n b t d -> n b t',  # [N, B, T, D]
    proj.weight.squeeze(),  # [D]
    K
)
这里做的就是前面提到的计算layer level的注意力分数:$s_{i,t}^{(l)} = q_l^\top k_{i,t}$ 。
第四行,
h = torch.einsum(
    'n b t, n b t d -> b t d',
    logits.softmax(0),
    V
)
就是计算分配给token在第 $i$ 层对应信息的权重:$h_{l,t} = \sum_i \alpha_{i,t}^{(l)} v_{i,t}$ 。
This completes the progression from GPT-2 to KimiK3.
The central change is not scale alone. Each architectural step changes what the model stores, how it updates that state, or how it retrieves information that a fixed-size state cannot preserve.
KimiK3 combines constant-state recurrent memory, periodic softmax retrieval, sparse expert capacity, and selective depth-wise residual access. The result is a system that spends additional capacity where it has a specific functional role.
In essence, a fixed-capacity associative memory (fixed dimensions) needs an eviction policy, since a purely additive linear operation eventually adds interference once at capacity. To that end, learned selection, like gating, routing, or decay, is necessary, and attention is the most effective selective-read mechanism.
终于,我们可以把所有的内容大概串起来,
                    Kimi K3
                       │
       ┌───────────────┼───────────────────┐
       │               │                   │
      KDA             MLA               AttnRes
       │               │                   │
fixed-size       token retrieval       depth retrieval
recurrent state        │                   │
       │               │                   │
       ↓               ↓                   ↓
“存什么?”         “查哪个token?”       “查哪层表示?”
       │               │                   │
gating/decay       softmax attention   softmax attention
再加上 MoE:
MoE
 ↓
“这个 token 用哪些计算能力?”
 ↓
expert routing
当模型变大,需要处理的信息变多后,我们必须回答:
- 什么应该留下?
- 什么应该忘掉?
- 什么应该读取?
- 什么应该忽略?
就像一个大公司,一个复杂的现代社会,需要更先进的管理组织和形式。于是现代架构大量出现:
gate
router
decay
attention
它们表面上是不同的模块和方法,本质上都在做一件事:
learned selective information flow
Source
- Original X post: https://x.com/waterloo_intern/status/2081762065392541951